Trending AI Posts & Hot Research Catchup - Page 1725
How to Try GPT-5.5 for Free in ChatGPT: Check Access the Right Way
12 sources0The legitimate free route is ChatGPT: sign in or create a free account, open a new chat, and select GPT 5.5 if it appears.
Claude Opus 4.7 vs. GPT-5.5: agents, long context and enterprise APIs
21 sources0For API procurement, long context agents or enterprise deployment, Claude Opus 4.7 is easier to evaluate from public documentation: Anthropic lists a 1M context window with no long context premium, multi clo...
Claude Opus 4.7 vs. GPT-5.5: How to Read the Benchmarks Before You Choose
11 sources0There is not enough same condition public data to declare an overall winner: Opus 4.7 leads GDPval AA at 1,753 Elo, while GPT 5.5 high, low and non reasoning score 59, 51 and 41 on the Artificial Analysis In...
Claude Opus 4.7 vs GPT-5.5: Best Model for Coding, Agents, Research and Design
17 sources0Claude Opus 4.7 is the better supported first trial for coding and tool heavy agents: Vellum reports 87.6% on SWE bench Verified and 77.3% on MCP Atlas.
Claude Opus 4.7 vs. GPT-5.5: the enterprise deployment question
25 sources0Claude Opus 4.7 is easier to put into an API proof of concept now: Anthropic lists API and cloud platform availability, $5/$25 per million input/output token pricing, a 1M context window and documented long...
Claude Opus 4.7 vs GPT-5.5 Spud: No Benchmark Winner Yet
24 sources0No reliable winner can be named: Claude Opus 4.7 is verified in Anthropic’s documentation, while GPT 5.5 Spud is not verified here by a primary OpenAI source.
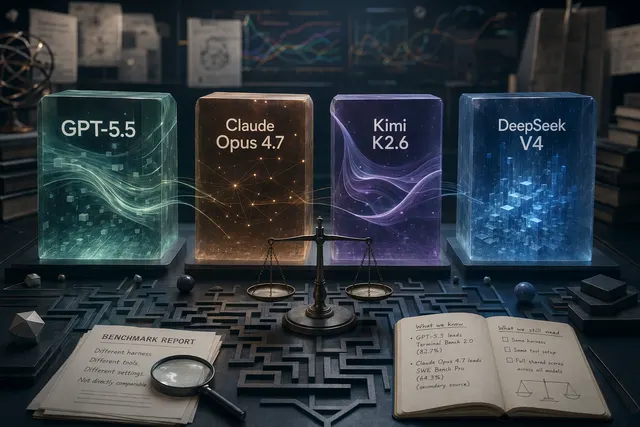
GPT-5.5 vs Claude Opus 4.7 vs Kimi K2.6 vs DeepSeek V4-Pro: Benchmark Guide
23 sources0There is no defensible single champion because the cited numbers come from different harnesses, source layers and tool settings.
How to try GPT-5.5 now: ChatGPT, Codex and API availability
15 sources0The fastest official routes to try GPT 5.5 are ChatGPT and Codex. OpenAI says API availability is still “coming soon.” [1][20]
GPT-5.5 vs Claude Opus 4.7 vs DeepSeek V4 vs Kimi K2.6: Which Model Wins Which Benchmark?
24 sources0There is no clean overall winner from public benchmarks alone. GPT 5.5 leads the cited Terminal Bench 2.0 numbers at 82.7%, while Claude Opus 4.7 leads SWE Bench Pro at 64.3% and SWE Bench Verified at 87.6%...
Claude Opus 4.7 benchmarks: what 87.6% on SWE-bench Verified really means
12 sources0AWS reports Claude Opus 4.7 at 87.6% on SWE bench Verified, based on Anthropic data, making it the standout public figure for agentic coding use cases [7].
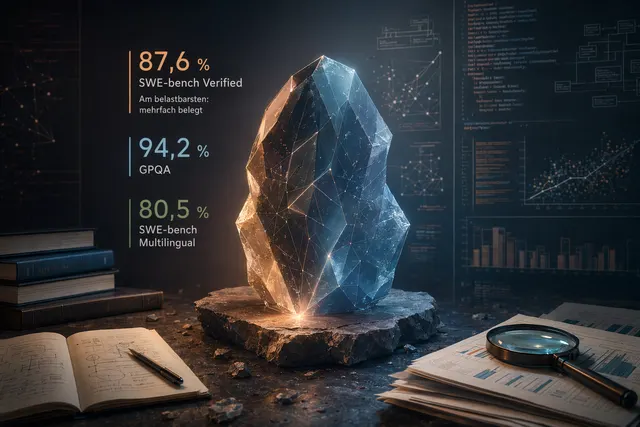
Claude Opus 4.7 benchmarks: SWE-bench, GPQA, and caveats
16 sources0The main public benchmark numbers are 87.6% on SWE bench Verified, 94.2% on GPQA and 80.5% on SWE bench Multilingual.
Claude Mythos Preview benchmark: what 93.9% on SWE-bench really means
17 sources0The most cited Claude Mythos Preview benchmark result is 93.9% on SWE bench, a software engineering evaluation that is most relevant to coding tasks and agent style workflows [1][2].