Trending AI Posts & Hot Research Catchup - Page 1702
Where to Try DeepSeek-V4 Preview: Web, App and API
12 sources0DeepSeek says DeepSeek V4 Preview is available on three official channels: web, app and API.[5][7]
Where to Try Claude Opus 4.7: Claude, API, Bedrock, Vertex AI, Foundry and Copilot
12 sources0Claude Opus 4.7 is listed by Anthropic with an April 16, 2026 announcement and is available through Claude products, the Claude API, Amazon Bedrock, Google Cloud Vertex AI and Microsoft Foundry; GitHub Copil...
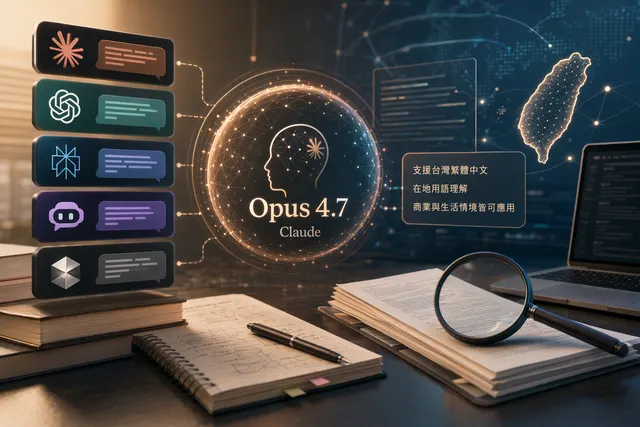
5 AI Apps to Try First: How to Verify Claude Opus 4.7 Claims
11 sources0A sensible trial order is Claude, ChatGPT, Perplexity, Poe and Cursor — but the available sources only show the name Claude Opus 4.7 in third party pages, Medium and YouTube content, not confirmed official s...
Claude Opus 4.7 vs. Opus 4.6 vs. Sonnet 4.6: Which model should run your coding agents?
13 sources0Use Claude Sonnet 4.6 as the default for broad production traffic when speed and cost matter; use Claude Opus 4.7 as the escalation model for hard coding agent, multi step, long output or vision heavy work.
GPT-5.5 vs Claude Opus 4.7 vs Kimi K2.6 vs DeepSeek V4: Benchmark Comparison
22 sources0Use GPT 5.5 for terminal heavy coding agents, Claude Opus 4.7 for software repair benchmarks, Kimi K2.6 for open weight deployment, and DeepSeek V4 Pro Max as a cost sensitive test case.
Ballast Water Management Audit Matrix for BWM Convention Compliance
9 sources0Use a regulation first matrix: B 1 for the approved BWMP, B 2 and Appendix II for the BWRB, D 1 for exchange, D 2 for treatment, D 3 for BWMS approval and E 1/E 2 for surveys and certification.
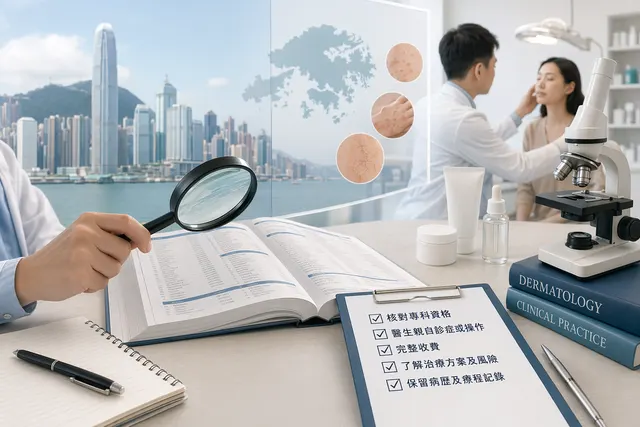
How to Check a Hong Kong Dermatologist: Names, Services and Fees
3 sources0Use the Hong Kong College of Dermatologists current members list first to match a doctor’s English and Chinese names; it is useful for name checking, not as a ranking or fee schedule[15].
Laundrin Room Diffuser vs. Fragrance Gel: Which to Buy?
4 sources0For most rooms, choose the Laundrin room diffuser: Laundrin describes it as a consistent, flame free and spray free scent option, and listings cite fragrance for up to 3 months; gel details are not verified...
IVF Embryo Transfer Date Selection for May 2026: May 6 Ranks First
6 sources0If May 5, 6 and 7, 2026 are all medically suitable for embryo transfer, a traditional Tong Sheng and bazi style reading ranks May 6 first, May 5 second, and May 7 not as the first choice.
GPT-5.5 vs Claude Opus 4.7 vs DeepSeek V4 vs Kimi K2.6: How to Read the Benchmarks
15 sources0The clearest four model overlap is Terminal Bench 2.0: GPT 5.5 82.7%, Claude Opus 4.7 69.4%, DeepSeek V4 Pro Max 67.9% and Kimi K2.6 Thinking 66.7%.[29][30][6]
GPT-5.5 benchmarks: what 84.9% on GDPval actually means
10 sources0The cleanest short benchmark for GPT 5.5 is 84.9% on GDPval, which OpenAI describes as testing well specified knowledge work across 44 occupations.[1]
GPT-5.5 vs. Claude Opus 4.7: Coding Has a Front-Runner, Creativity Does Not
19 sources0Coding is the clearest category: GPT 5.5 has the stronger public case, including a reported 82.7% Terminal Bench result and a slight edge on tool heavy SWE Bench Verified tasks.