GPT-5.5 benchmarks: what 84.9% on GDPval actually means
The cleanest short benchmark for GPT 5.5 is 84.9% on GDPval, which OpenAI describes as testing well specified knowledge work across 44 occupations.[1] Other figures, such as 73.1% on Expert SWE and 80.5% on BixBench, refer to different task areas and should not be compared directly with GDPval.[8][10] For a broader...
Published byEdited with GPT-5.5Images generated with GPT Image 2
The cleanest short benchmark for GPT 5.5 is 84.9% on GDPval, which OpenAI describes as testing well specified knowledge work across 44 occupations.[1]
Other figures, such as 73.1% on Expert SWE and 80.5% on BixBench, refer to different task areas and should not be compared directly with GDPval.[8][10]
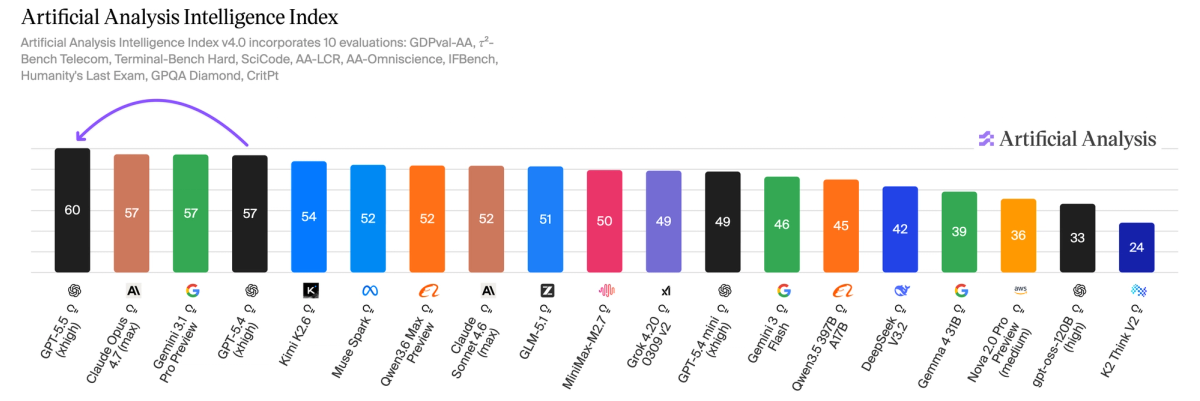
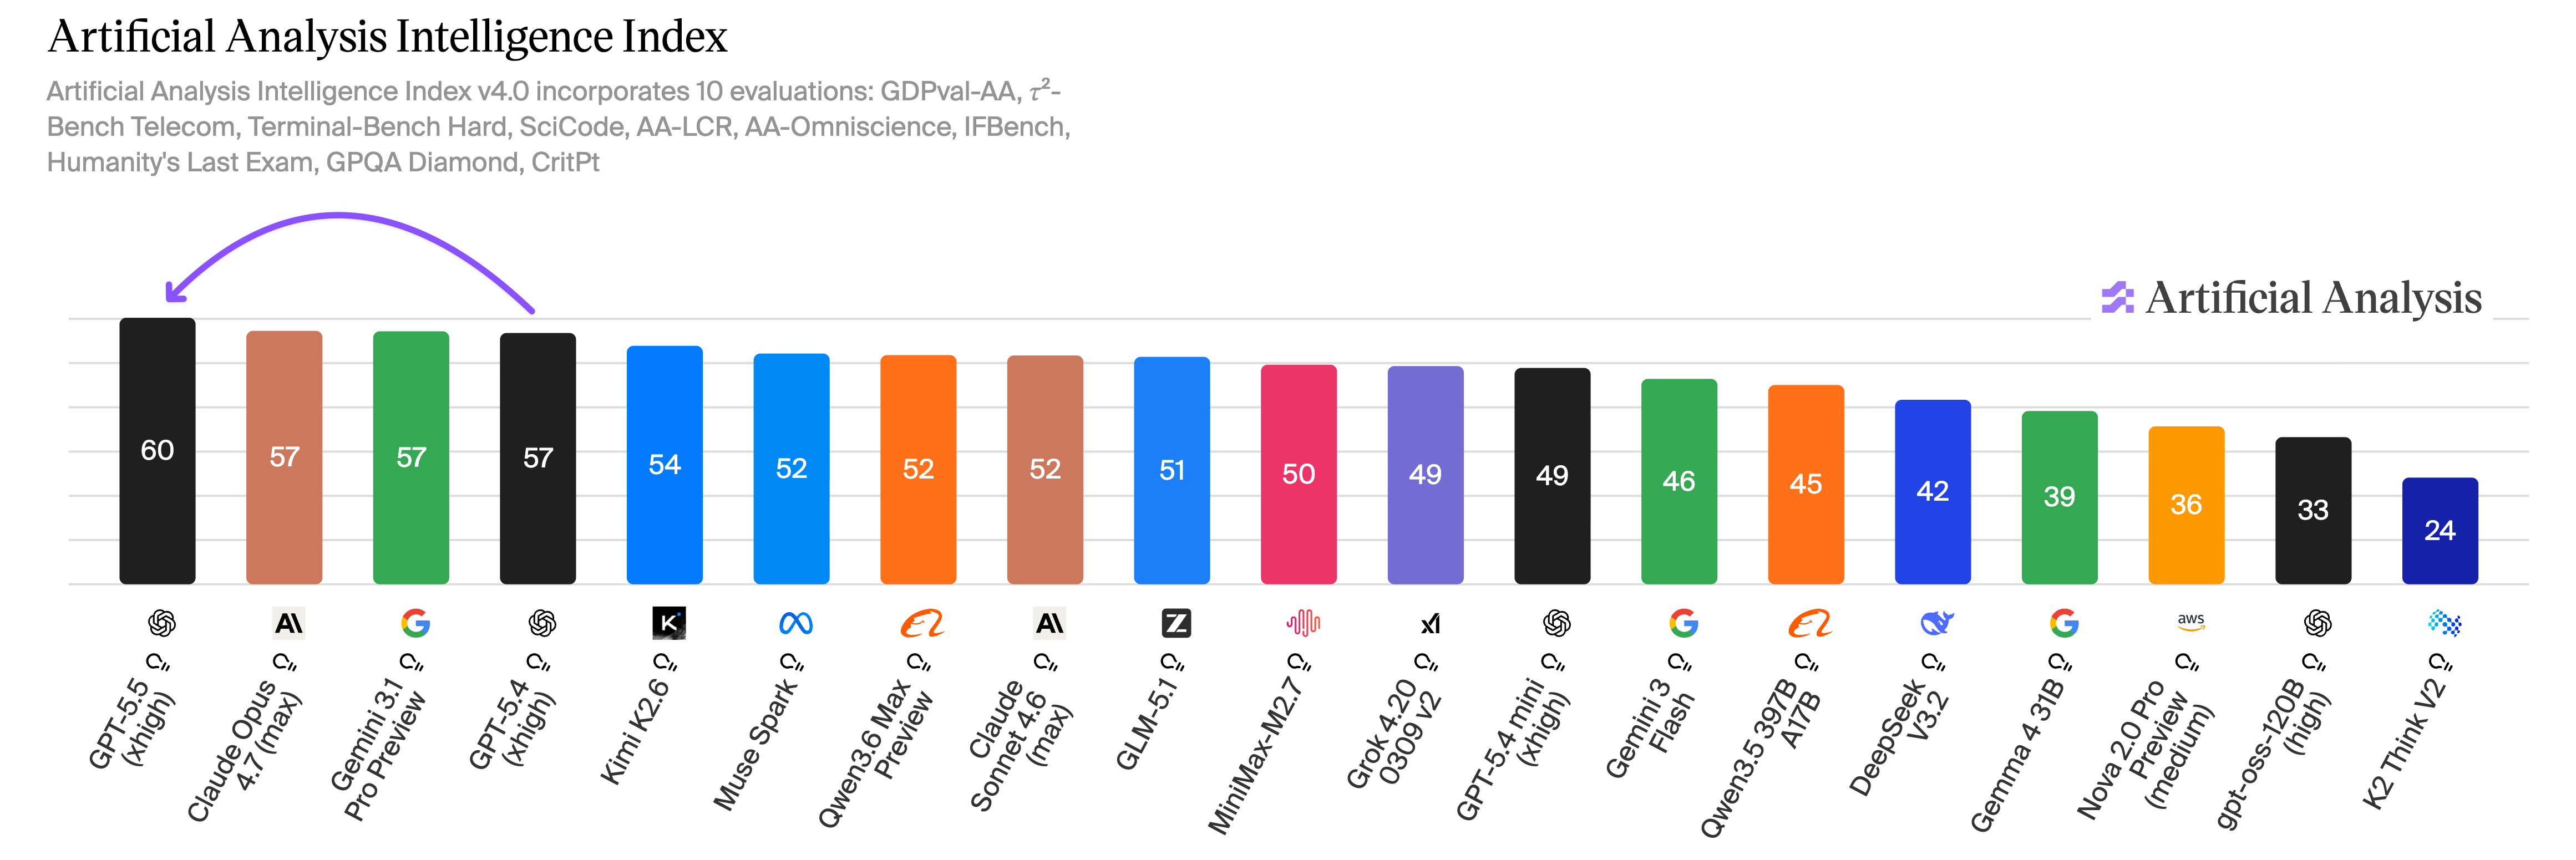
For a broader third party comparison, Artificial Analysis says GPT 5.5 leads its Intelligence Index by three points, though it does not win every individual evaluation.[3]
GPT-5.5-Benchmark erklärt: Was 84,9 % auf GDPval wirklich bedeutenKI-generierte Illustration zum Vergleich von GPT-5.5-Benchmarks.
AI Prompt
Create a landscape editorial hero image for this Studio Global article: GPT-5.5-Benchmark erklärt: Was 84,9 % auf GDPval wirklich bedeuten. Article summary: Für eine knappe, belastbare Einordnung ist 84,9 % auf GDPval der beste GPT 5.5 Wert: OpenAI nennt ihn selbst und beschreibt GDPval als Test für klar spezifizierte Wissensarbeit über 44 Berufe.. Topic tags: ai, openai, chatgpt, gpt 5, benchmarks. Reference image context from search candidates: Reference image 1: visual subject " GPT-5.5 tops the Artificial Analysis Intelligen" source context "OpenAI's GPT-5.5 is the new leading AI model - Artificial Analysis" Reference image 2: visual subject " GPT-5.5 tops the Artificial Analysis Intelligen" source context "OpenAI's GPT-5.5 is the new leading AI model - Artificial Analysis" Reference image 2: visual subject "![Image 1](https://cdn.sanity.io/images/6vfeftx9/articles/9052d745e6337cd4369bde9219bcf511bebec944-4644x1551.png?
openai.com
If you want one short benchmark number for GPT-5.5, the most defensible answer is this: GPT-5.5 scores 84.9% on GDPval, according to OpenAI. OpenAI describes GDPval as a benchmark that tests AI agents’ ability to produce well-specified knowledge work across 44 occupations.
That number matters because it is official, clearly stated and tied to a defined task type. But it is not a universal grade for “how smart” GPT-5.5 is. It says most about structured, workplace-style knowledge tasks—not necessarily software engineering, bioinformatics, legal reasoning or every other specialised use case.
The headline benchmark: 84.9% on GDPval
The most precise one-line version is:
GPT-5.5 scores 84.9% on GDPval, a benchmark OpenAI says tests agents’ ability to produce well-specified knowledge work across 44 occupations.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "GPT-5.5 benchmarks: what 84.9% on GDPval actually means"?
The cleanest short benchmark for GPT 5.5 is 84.9% on GDPval, which OpenAI describes as testing well specified knowledge work across 44 occupations.[1]
What are the key points to validate first?
The cleanest short benchmark for GPT 5.5 is 84.9% on GDPval, which OpenAI describes as testing well specified knowledge work across 44 occupations.[1] Other figures, such as 73.1% on Expert SWE and 80.5% on BixBench, refer to different task areas and should not be compared directly with GDPval.[8][10]
What should I do next in practice?
For a broader third party comparison, Artificial Analysis says GPT 5.5 leads its Intelligence Index by three points, though it does not win every individual evaluation.[3]
For general readers, the key phrase is well-specified knowledge work. In plain English, GDPval is about whether a model can produce defined work outputs across a range of professional tasks. It is useful for judging GPT-5.5 as a work-oriented model, but it should not be treated as a single all-purpose scorecard.
The main reported numbers, side by side
Benchmark or comparison
Reported result
What it measures
How to read it
GDPval
84.9%
Well-specified knowledge work across 44 occupations
The strongest short benchmark because OpenAI states it directly in its GPT-5.5 announcement.
Expert-SWE
73.1%
Coding tasks; reported as OpenAI’s internal evaluation for tasks with an estimated 20-hour completion time
More relevant to software development than GDPval, but not directly comparable with it.
BixBench
80.5%
Real-world bioinformatics tasks
Relevant for bioinformatics, but in the available source set it is less directly evidenced than OpenAI’s GDPval figure.
Artificial Analysis Intelligence Index
No. 1, by 3 points
A third-party model index from Artificial Analysis
Useful for broad model comparison, but it is not a single official OpenAI benchmark.
Why the percentages should not be compared as if they are one leaderboard
Numbers such as 84.9%, 73.1% and 80.5% look easy to rank. That can be misleading.
84.9% on GDPval refers to specified knowledge work across many occupations.
73.1% on Expert-SWE refers to coding tasks in an internal evaluation, according to a report.
80.5% on BixBench refers to a real-world bioinformatics benchmark.
So the better question is not “Which percentage is highest?” It is “Which benchmark matches the job?” For general workplace knowledge tasks, GDPval is the better reference point. For software engineering, Expert-SWE is closer to the target. For bioinformatics, BixBench is more relevant to the domain.
What the Artificial Analysis result adds
Artificial Analysis says GPT-5.5 tops its Intelligence Index by three points. It also says OpenAI leads five of its headline evaluations and places second to Gemini 3.1 Pro Preview on three others.
That distinction matters. A No. 1 ranking in an external index does not mean a model wins every individual test. It means GPT-5.5 comes out ahead overall under that third-party index’s methodology.
Be careful with isolated headline scores
Some reports cite additional GPT-5.5 figures, including 91.7% in connection with legal AI capabilities and 82.7% in the context of agentic coding. Those numbers may be useful for their specific areas, but they are weaker as a general answer unless the benchmark design, comparison group and measurement target are just as clear.
That is why 84.9% on GDPval remains the cleanest general-purpose benchmark to quote: it is directly stated by OpenAI and tied to a defined evaluation area.
Which GPT-5.5 benchmark should you cite?
Use the benchmark that matches the context:
General knowledge work: 84.9% on GDPval.
Software engineering: 73.1% on Expert-SWE.
Bioinformatics: 80.5% on BixBench, with a note that the sourcing is less direct in the available materials.
Broad model ranking: No. 1 in the Artificial Analysis Intelligence Index, by three points.
Bottom line
The best short benchmark for GPT-5.5 is 84.9% on GDPval. It is official, easy to cite and clearly tied to well-specified knowledge work across 44 occupations. Other scores may matter more for coding, science or specialised professional tasks, but they should always be named with the benchmark they come from.
mexc.com
OpenAI’s GPT-5.5 Launches With 91.7% Benchmark Score | MEXC News
For general readers, the key phrase is well-specified knowledge work. In plain English, GDPval is about whether a model can produce defined work outputs across a range of professional tasks. It is useful for judging GPT-5.5 as a work-oriented model, but it should not be treated as a single all-purpose scorecard.
The main reported numbers, side by side
Benchmark or comparison
Reported result
What it measures
How to read it
GDPval
84.9%
Well-specified knowledge work across 44 occupations
The strongest short benchmark because OpenAI states it directly in its GPT-5.5 announcement.
Expert-SWE
73.1%
Coding tasks; reported as OpenAI’s internal evaluation for tasks with an estimated 20-hour completion time
More relevant to software development than GDPval, but not directly comparable with it.
BixBench
80.5%
Real-world bioinformatics tasks
Relevant for bioinformatics, but in the available source set it is less directly evidenced than OpenAI’s GDPval figure.
Artificial Analysis Intelligence Index
No. 1, by 3 points
A third-party model index from Artificial Analysis
Useful for broad model comparison, but it is not a single official OpenAI benchmark.
Why the percentages should not be compared as if they are one leaderboard
Numbers such as 84.9%, 73.1% and 80.5% look easy to rank. That can be misleading.
84.9% on GDPval refers to specified knowledge work across many occupations.
73.1% on Expert-SWE refers to coding tasks in an internal evaluation, according to a report.
80.5% on BixBench refers to a real-world bioinformatics benchmark.
So the better question is not “Which percentage is highest?” It is “Which benchmark matches the job?” For general workplace knowledge tasks, GDPval is the better reference point. For software engineering, Expert-SWE is closer to the target. For bioinformatics, BixBench is more relevant to the domain.
What the Artificial Analysis result adds
Artificial Analysis says GPT-5.5 tops its Intelligence Index by three points. It also says OpenAI leads five of its headline evaluations and places second to Gemini 3.1 Pro Preview on three others.
That distinction matters. A No. 1 ranking in an external index does not mean a model wins every individual test. It means GPT-5.5 comes out ahead overall under that third-party index’s methodology.
Be careful with isolated headline scores
Some reports cite additional GPT-5.5 figures, including 91.7% in connection with legal AI capabilities and 82.7% in the context of agentic coding. Those numbers may be useful for their specific areas, but they are weaker as a general answer unless the benchmark design, comparison group and measurement target are just as clear.
That is why 84.9% on GDPval remains the cleanest general-purpose benchmark to quote: it is directly stated by OpenAI and tied to a defined evaluation area.
Which GPT-5.5 benchmark should you cite?
Use the benchmark that matches the context:
General knowledge work: 84.9% on GDPval.
Software engineering: 73.1% on Expert-SWE.
Bioinformatics: 80.5% on BixBench, with a note that the sourcing is less direct in the available materials.
Broad model ranking: No. 1 in the Artificial Analysis Intelligence Index, by three points.
Bottom line
The best short benchmark for GPT-5.5 is 84.9% on GDPval. It is official, easy to cite and clearly tied to well-specified knowledge work across 44 occupations. Other scores may matter more for coding, science or specialised professional tasks, but they should always be named with the benchmark they come from.
mexc.com
OpenAI’s GPT-5.5 Launches With 91.7% Benchmark Score | MEXC News