OpenAI, Claude, DeepSeek, Gemini or Grok: how content teams should split the work
There is not enough public evidence to crown one model as the universal best for content marketing. API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
Published byEdited with GPT-5.5Images generated with GPT Image 2
There is not enough public evidence to crown one model as the universal best for content marketing.
API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
Model tests should measure publishable output, editing time, brand consistency, factual error rate, formatting reliability and task cost—not just whether the first draft sounds polished.
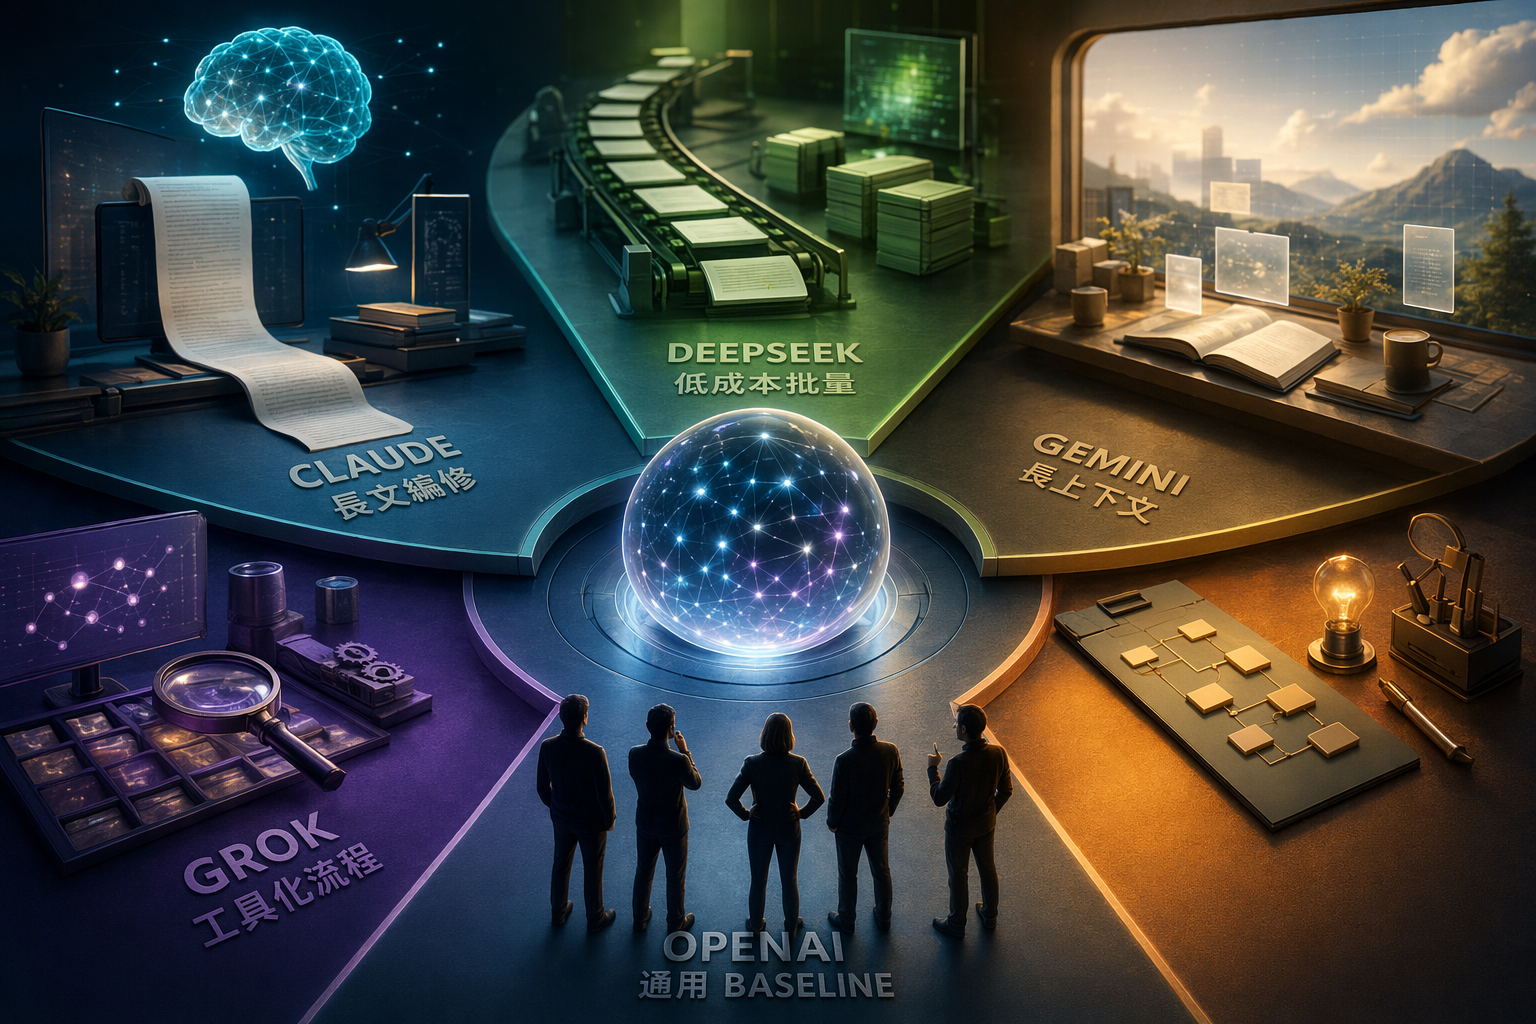
OpenAI、Claude、DeepSeek、Gemini、Grok 怎麼選?內容創作與行銷團隊指南AI 生成示意圖:內容團隊在研究、SEO、長文編修與自動化流程中比較不同 AI 模型。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: OpenAI、Claude、DeepSeek、Gemini、Grok 怎麼選?內容創作與行銷團隊指南. Article summary: 截至 2026 年可引用的公開資料,沒有證據支持五者中有單一內容行銷冠軍;更務實的分工是 OpenAI 當通用 baseline、Claude 測長文編修、DeepSeek 跑低成本批量、Gemini 處理長上下文、Grok 評估工具化流程。最後仍要用自家 KPI 實測。. Topic tags: ai, content marketing, seo, openai, claude. Reference image context from search candidates: Reference image 1: visual subject "# 2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂. 2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂 全解析,付費、應用與安全性一次看懂"). 近幾年有多款大型語言模型 (LLM) 接連問世,對一般用戶來說,到底哪一款最適合日常需求。本次整理 5 款主流 LLM,分別為 GPT‑" source context "2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂 | 鏈新聞 ABMedia" Reference image 2: visual subject "## Loading. ## Loading. # 生命不息,折腾不止. ## 要有最朴素的生活,与最遥远的梦想。即使明日天寒地冻、路远马亡。. # 【译】Grok 3 vs ChatGPT vs DeepSeek vs Claude vs Gemini:2025年2月哪款AI最好?. 人工智能(AI)的进步速度前所未有,几乎每周都有新的模型和技术问世。20" source c
openai.com
Choosing an AI model for content creation and marketing is easy to get wrong if you start with a leaderboard. Public sources can help compare API pricing, context windows, prompt caching and server-side tools, but they do not prove that any one model will reliably deliver higher SEO rankings, better ad conversion or more consistent brand voice. The more useful question is: which model fits which part of your workflow?
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "OpenAI, Claude, DeepSeek, Gemini or Grok: how content teams should split the work"?
There is not enough public evidence to crown one model as the universal best for content marketing.
What are the key points to validate first?
There is not enough public evidence to crown one model as the universal best for content marketing. API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
What should I do next in practice?
Model tests should measure publishable output, editing time, brand consistency, factual error rate, formatting reliability and task cost—not just whether the first draft sounds polished.
OpenAI, Claude, DeepSeek, Gemini or Grok: how content teams should split the work
There is not enough public evidence to crown one model as the universal best for content marketing. API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
Published byEdited with GPT-5.5Images generated with GPT Image 2
There is not enough public evidence to crown one model as the universal best for content marketing.
API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
Model tests should measure publishable output, editing time, brand consistency, factual error rate, formatting reliability and task cost—not just whether the first draft sounds polished.
OpenAI、Claude、DeepSeek、Gemini、Grok 怎麼選?內容創作與行銷團隊指南AI 生成示意圖:內容團隊在研究、SEO、長文編修與自動化流程中比較不同 AI 模型。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: OpenAI、Claude、DeepSeek、Gemini、Grok 怎麼選?內容創作與行銷團隊指南. Article summary: 截至 2026 年可引用的公開資料,沒有證據支持五者中有單一內容行銷冠軍;更務實的分工是 OpenAI 當通用 baseline、Claude 測長文編修、DeepSeek 跑低成本批量、Gemini 處理長上下文、Grok 評估工具化流程。最後仍要用自家 KPI 實測。. Topic tags: ai, content marketing, seo, openai, claude. Reference image context from search candidates: Reference image 1: visual subject "# 2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂. 2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂 全解析,付費、應用與安全性一次看懂"). 近幾年有多款大型語言模型 (LLM) 接連問世,對一般用戶來說,到底哪一款最適合日常需求。本次整理 5 款主流 LLM,分別為 GPT‑" source context "2026 最新五大主流 AI 語言模型 (LLM) 全解析,付費、應用與安全性一次看懂 | 鏈新聞 ABMedia" Reference image 2: visual subject "## Loading. ## Loading. # 生命不息,折腾不止. ## 要有最朴素的生活,与最遥远的梦想。即使明日天寒地冻、路远马亡。. # 【译】Grok 3 vs ChatGPT vs DeepSeek vs Claude vs Gemini:2025年2月哪款AI最好?. 人工智能(AI)的进步速度前所未有,几乎每周都有新的模型和技术问世。20" source c
openai.com
Choosing an AI model for content creation and marketing is easy to get wrong if you start with a leaderboard. Public sources can help compare API pricing, context windows, prompt caching and server-side tools, but they do not prove that any one model will reliably deliver higher SEO rankings, better ad conversion or more consistent brand voice. The more useful question is: which model fits which part of your workflow?
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "OpenAI, Claude, DeepSeek, Gemini or Grok: how content teams should split the work"?
There is not enough public evidence to crown one model as the universal best for content marketing.
What are the key points to validate first?
There is not enough public evidence to crown one model as the universal best for content marketing. API costs should be estimated separately for input tokens and output tokens: long briefs, transcripts and competitor research are input heavy, while ad variants, product descriptions and social rewrites are output heavy.
What should I do next in practice?
Model tests should measure publishable output, editing time, brand consistency, factual error rate, formatting reliability and task cost—not just whether the first draft sounds polished.
The short answer: build a model mix, not a single winner
Content team need
Test first
Why it belongs on the shortlist
Watch out for
General research, content briefs, campaign planning, drafts and final polish
OpenAI
Third-party pricing tables list multiple OpenAI model tiers with different input/output pricing and context options; TLDL describes the GPT-4.1 family as offering a 1M-token context window at mid-range pricing.
Treat it as a baseline, not proof that it wins every content task.
Anthropic’s official Claude pricing documentation separates Base Input Tokens, Cache Writes, Cache Hits and Output Tokens, which matters when teams repeatedly reuse brand guidelines, templates or review rules.
Test publishable rate, editing time and brand consistency—not just first-draft style.
High-volume SEO drafts, product descriptions and ad copy variants
DeepSeek
DeepSeek has official Models & Pricing documentation; a third-party 2026 guide describes DeepSeek chat/reasoning unified pricing at about $0.28 per million input tokens and $0.42 per million output tokens, with a claimed 94–96% cost reduction versus OpenAI o3 or GPT-4.1.
Low cost is useful for draft volume, but fact-checking and brand review still matter.
Very long briefs, competitor research, transcripts and keyword packs
Gemini
MorphLLM lists Gemini 2.5 Flash with a 1M context window, $2.50 per million output tokens and a free tier; TLDL places Gemini 2.5 Pro among the highest context-window options at 2M tokens.
The Gemini details cited here come mainly from third-party comparisons, so verify current vendor documentation before buying.
Tool calls, automated content operations and server-side workflows
Grok
xAI’s official documentation provides Models and Pricing and lists separate Tools Pricing for server-side tools; TLDL also says xAI has two models with 2M-token context windows.
Worth testing in tool-driven pipelines, but the cited sources do not prove Grok consistently beats OpenAI or Claude on general marketing copy quality.
Start with cost: input-heavy and output-heavy work are different
Text generation APIs are typically priced by token usage. Providers set pricing tiers per million tokens. Input tokens are the text you send to the model—your prompt, documents or context—while output tokens are the text the model generates.
That split matters because content work usually falls into two cost patterns:
Input-heavy tasks: competitor-page analysis, interview or sales-call transcript summaries, SEO keyword pack analysis, product documentation review and long research briefs. The main cost pressure comes from how much material you feed into the model.
Output-heavy tasks: ad headlines, product descriptions, FAQs, social posts, multilingual rewrites and A/B copy variants. Here, output-token pricing can dominate once the team starts generating at scale.
If your team sends the same brand voice guide, legal restrictions, SEO template or editorial checklist with every request, also look closely at prompt caching. Claude’s official pricing documentation separates cache writes from cache hits, which means repeated context can affect both workflow design and cost planning.
OpenAI: the general-purpose baseline
OpenAI is a sensible starting baseline for many marketing teams. That does not mean public data proves it is the best model for every content job. The more practical reason is that third-party pricing tables show several OpenAI model tiers, making it easier to reserve stronger models for strategy, synthesis and final polish while using lower-cost models for summaries, rewrites and batch variants.
TLDL describes the GPT-4.1 family as offering a 1M-token context window at mid-range pricing, which makes it a reasonable candidate for long briefs, research summaries and campaign planning tests. The caveat: the OpenAI pricing and context-window details cited here come primarily from third-party aggregators rather than direct official documentation.
Useful first tests include SEO pillar-page outlines, campaign messaging, research synthesis, long-form drafts, headline variants, email sections and repurposed social posts. Keep quality and cost in separate columns during evaluation, because context windows and per-million-token pricing can vary across models from the same provider.
Claude: long-form editing and brand voice deserve a serious test
For content teams, Claude is especially worth testing in long-form editing and rules-driven editorial workflows. Anthropic’s official Claude API pricing documentation lists Base Input Tokens, Cache Writes, Cache Hits and Output Tokens, which is helpful for teams that repeatedly use brand voice rules, editorial standards, legal constraints or article templates.
That does not mean Claude should be reduced to simply the model with the nicest prose. A better test is whether it improves the parts of the workflow that cost human editors the most time: long-form rewrites, white paper summaries, brand voice alignment, editorial checklist review and content structure revision.
Judge the results by publishable rate, human editing time and error rate—not just whether the first draft reads smoothly.
DeepSeek: low-cost drafting and large-scale variants
DeepSeek’s obvious appeal is cost. DeepSeek provides official Models & Pricing documentation, and DecodesFuture’s 2026 pricing guide describes DeepSeek chat/reasoning unified pricing at about $0.28 per million input tokens and $0.42 per million output tokens, with a claimed 94–96% reduction compared with OpenAI o3 or GPT-4.1.
That makes DeepSeek a strong candidate for the front end of a content production workflow: long-tail SEO drafts, product descriptions, FAQs, ad copy variants, first-pass localization and social post drafts.
The operational rule is simple: do not confuse cheap output with publishable output. The more you scale production, the more you need clear fact-checking, brand review and formatting checks.
Gemini: a candidate for long-context source material
Gemini’s main selection argument in the cited sources is long context. MorphLLM lists Gemini 2.5 Flash with a 1M context window, $2.50 per million output tokens and a free tier; TLDL lists Gemini 2.5 Pro among the top context-window options at 2M tokens.
For marketing teams, long context is useful when the input is the bottleneck: multiple competitor pages, sales-call transcripts, SEO keyword packs, product documents, customer interviews and existing brand content. Many high-quality content tasks fail not because the model cannot write, but because it has not absorbed enough background material.
Gemini therefore belongs in tests for large-input workflows. Just be careful with procurement: the Gemini specifications cited here come mainly from third-party comparisons, so final limits and pricing should be checked against the provider documents your team will actually use.
Grok: a workflow candidate for tools and automation
Grok should not be judged only by one-off copy outputs. xAI’s official documentation provides Models and Pricing and separates Tools Pricing for server-side tools, which is relevant for teams connecting models to tools, data sources or automated content pipelines.
TLDL also says xAI has two models with 2M-token context windows and distinguishes Grok 4 from Grok 4.1 Fast. Based on the cited sources, however, it would be too strong to claim that Grok consistently outperforms OpenAI or Claude on general marketing copy quality.
The safer positioning is this: if your workflow depends on tool calls, data connections or automated task chains, Grok should be on the test list.
How to run a fair model test
Public pricing and specification tables can narrow the shortlist, but they cannot choose the final model for you. Run a small, controlled test using the same brand materials and the same constraints for every candidate model.
Try these five tasks:
SEO brief: provide keywords, search intent, competitor summaries and product information. Ask for an outline, section angles and claims that need verification.
Long-form edit: provide a draft and brand voice guide. Ask the model to rewrite while preserving facts and explaining major changes.
Ad copy variants: generate multiple headlines, primary text options and CTAs, then check brand fit and platform constraints.
Content repurposing: turn a long article into LinkedIn, X, Threads, newsletter and short-video script material.
Fact-checking and uncertainty: ask the model to flag claims that need verification rather than confidently filling gaps.
Do not score only for fluency. Track publishable rate, editing time, brand consistency, factual errors, formatting stability, cost per task and projected cost at volume. Because API costs depend separately on input and output tokens, estimate long-input tasks and high-volume generation tasks separately.
The most practical starting lineup
If you need a fast starting point, use OpenAI as the general baseline, Claude for long-form and brand editing, DeepSeek for low-cost batch generation, Gemini for very long context and Grok for tool-based workflows.
That is not an absolute ranking of model intelligence. It is a testing matrix. The best model for your team will be decided by your language, market, brand rules, review process and content KPIs.
The short answer: build a model mix, not a single winner
Content team need
Test first
Why it belongs on the shortlist
Watch out for
General research, content briefs, campaign planning, drafts and final polish
OpenAI
Third-party pricing tables list multiple OpenAI model tiers with different input/output pricing and context options; TLDL describes the GPT-4.1 family as offering a 1M-token context window at mid-range pricing.
Treat it as a baseline, not proof that it wins every content task.
Anthropic’s official Claude pricing documentation separates Base Input Tokens, Cache Writes, Cache Hits and Output Tokens, which matters when teams repeatedly reuse brand guidelines, templates or review rules.
Test publishable rate, editing time and brand consistency—not just first-draft style.
High-volume SEO drafts, product descriptions and ad copy variants
DeepSeek
DeepSeek has official Models & Pricing documentation; a third-party 2026 guide describes DeepSeek chat/reasoning unified pricing at about $0.28 per million input tokens and $0.42 per million output tokens, with a claimed 94–96% cost reduction versus OpenAI o3 or GPT-4.1.
Low cost is useful for draft volume, but fact-checking and brand review still matter.
Very long briefs, competitor research, transcripts and keyword packs
Gemini
MorphLLM lists Gemini 2.5 Flash with a 1M context window, $2.50 per million output tokens and a free tier; TLDL places Gemini 2.5 Pro among the highest context-window options at 2M tokens.
The Gemini details cited here come mainly from third-party comparisons, so verify current vendor documentation before buying.
Tool calls, automated content operations and server-side workflows
Grok
xAI’s official documentation provides Models and Pricing and lists separate Tools Pricing for server-side tools; TLDL also says xAI has two models with 2M-token context windows.
Worth testing in tool-driven pipelines, but the cited sources do not prove Grok consistently beats OpenAI or Claude on general marketing copy quality.
Start with cost: input-heavy and output-heavy work are different
Text generation APIs are typically priced by token usage. Providers set pricing tiers per million tokens. Input tokens are the text you send to the model—your prompt, documents or context—while output tokens are the text the model generates.
That split matters because content work usually falls into two cost patterns:
Input-heavy tasks: competitor-page analysis, interview or sales-call transcript summaries, SEO keyword pack analysis, product documentation review and long research briefs. The main cost pressure comes from how much material you feed into the model.
Output-heavy tasks: ad headlines, product descriptions, FAQs, social posts, multilingual rewrites and A/B copy variants. Here, output-token pricing can dominate once the team starts generating at scale.
If your team sends the same brand voice guide, legal restrictions, SEO template or editorial checklist with every request, also look closely at prompt caching. Claude’s official pricing documentation separates cache writes from cache hits, which means repeated context can affect both workflow design and cost planning.
OpenAI: the general-purpose baseline
OpenAI is a sensible starting baseline for many marketing teams. That does not mean public data proves it is the best model for every content job. The more practical reason is that third-party pricing tables show several OpenAI model tiers, making it easier to reserve stronger models for strategy, synthesis and final polish while using lower-cost models for summaries, rewrites and batch variants.
TLDL describes the GPT-4.1 family as offering a 1M-token context window at mid-range pricing, which makes it a reasonable candidate for long briefs, research summaries and campaign planning tests. The caveat: the OpenAI pricing and context-window details cited here come primarily from third-party aggregators rather than direct official documentation.
Useful first tests include SEO pillar-page outlines, campaign messaging, research synthesis, long-form drafts, headline variants, email sections and repurposed social posts. Keep quality and cost in separate columns during evaluation, because context windows and per-million-token pricing can vary across models from the same provider.
Claude: long-form editing and brand voice deserve a serious test
For content teams, Claude is especially worth testing in long-form editing and rules-driven editorial workflows. Anthropic’s official Claude API pricing documentation lists Base Input Tokens, Cache Writes, Cache Hits and Output Tokens, which is helpful for teams that repeatedly use brand voice rules, editorial standards, legal constraints or article templates.
That does not mean Claude should be reduced to simply the model with the nicest prose. A better test is whether it improves the parts of the workflow that cost human editors the most time: long-form rewrites, white paper summaries, brand voice alignment, editorial checklist review and content structure revision.
Judge the results by publishable rate, human editing time and error rate—not just whether the first draft reads smoothly.
DeepSeek: low-cost drafting and large-scale variants
DeepSeek’s obvious appeal is cost. DeepSeek provides official Models & Pricing documentation, and DecodesFuture’s 2026 pricing guide describes DeepSeek chat/reasoning unified pricing at about $0.28 per million input tokens and $0.42 per million output tokens, with a claimed 94–96% reduction compared with OpenAI o3 or GPT-4.1.
That makes DeepSeek a strong candidate for the front end of a content production workflow: long-tail SEO drafts, product descriptions, FAQs, ad copy variants, first-pass localization and social post drafts.
The operational rule is simple: do not confuse cheap output with publishable output. The more you scale production, the more you need clear fact-checking, brand review and formatting checks.
Gemini: a candidate for long-context source material
Gemini’s main selection argument in the cited sources is long context. MorphLLM lists Gemini 2.5 Flash with a 1M context window, $2.50 per million output tokens and a free tier; TLDL lists Gemini 2.5 Pro among the top context-window options at 2M tokens.
For marketing teams, long context is useful when the input is the bottleneck: multiple competitor pages, sales-call transcripts, SEO keyword packs, product documents, customer interviews and existing brand content. Many high-quality content tasks fail not because the model cannot write, but because it has not absorbed enough background material.
Gemini therefore belongs in tests for large-input workflows. Just be careful with procurement: the Gemini specifications cited here come mainly from third-party comparisons, so final limits and pricing should be checked against the provider documents your team will actually use.
Grok: a workflow candidate for tools and automation
Grok should not be judged only by one-off copy outputs. xAI’s official documentation provides Models and Pricing and separates Tools Pricing for server-side tools, which is relevant for teams connecting models to tools, data sources or automated content pipelines.
TLDL also says xAI has two models with 2M-token context windows and distinguishes Grok 4 from Grok 4.1 Fast. Based on the cited sources, however, it would be too strong to claim that Grok consistently outperforms OpenAI or Claude on general marketing copy quality.
The safer positioning is this: if your workflow depends on tool calls, data connections or automated task chains, Grok should be on the test list.
How to run a fair model test
Public pricing and specification tables can narrow the shortlist, but they cannot choose the final model for you. Run a small, controlled test using the same brand materials and the same constraints for every candidate model.
Try these five tasks:
SEO brief: provide keywords, search intent, competitor summaries and product information. Ask for an outline, section angles and claims that need verification.
Long-form edit: provide a draft and brand voice guide. Ask the model to rewrite while preserving facts and explaining major changes.
Ad copy variants: generate multiple headlines, primary text options and CTAs, then check brand fit and platform constraints.
Content repurposing: turn a long article into LinkedIn, X, Threads, newsletter and short-video script material.
Fact-checking and uncertainty: ask the model to flag claims that need verification rather than confidently filling gaps.
Do not score only for fluency. Track publishable rate, editing time, brand consistency, factual errors, formatting stability, cost per task and projected cost at volume. Because API costs depend separately on input and output tokens, estimate long-input tasks and high-volume generation tasks separately.
The most practical starting lineup
If you need a fast starting point, use OpenAI as the general baseline, Claude for long-form and brand editing, DeepSeek for low-cost batch generation, Gemini for very long context and Grok for tool-based workflows.
That is not an absolute ranking of model intelligence. It is a testing matrix. The best model for your team will be decided by your language, market, brand rules, review process and content KPIs.
platform.claude.comPricing - Claude API Docs
pecollective.comCross-Provider LLM API Pricing Comparison (April 2026)
tldl.ioLLM API Pricing 2026 — Compare GPT-5, Claude 4, Gemini 2.5 ...
docs.x.aiModels and Pricing - xAI Docs
aipricingcomparison.comCompare OpenAI & Top LLM API Pricing Instantly - AI Pricing Comparison