Claude Opus 4.7 vs GPT-5.4, Gemini 3.1 Pro and Grok 4
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond... GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is posi...
Published byEdited with GPT-5.5Images generated with GPT Image 2
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond...
GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is positioned strongly for multimodal input, abstract reasoning and scientific benchmarks; Grok 4 stands out on the HLE hard rea...
Before buying or standardising on one model, test 5 to 10 real tasks and compare first pass success, tool errors, rework, latency and cost.
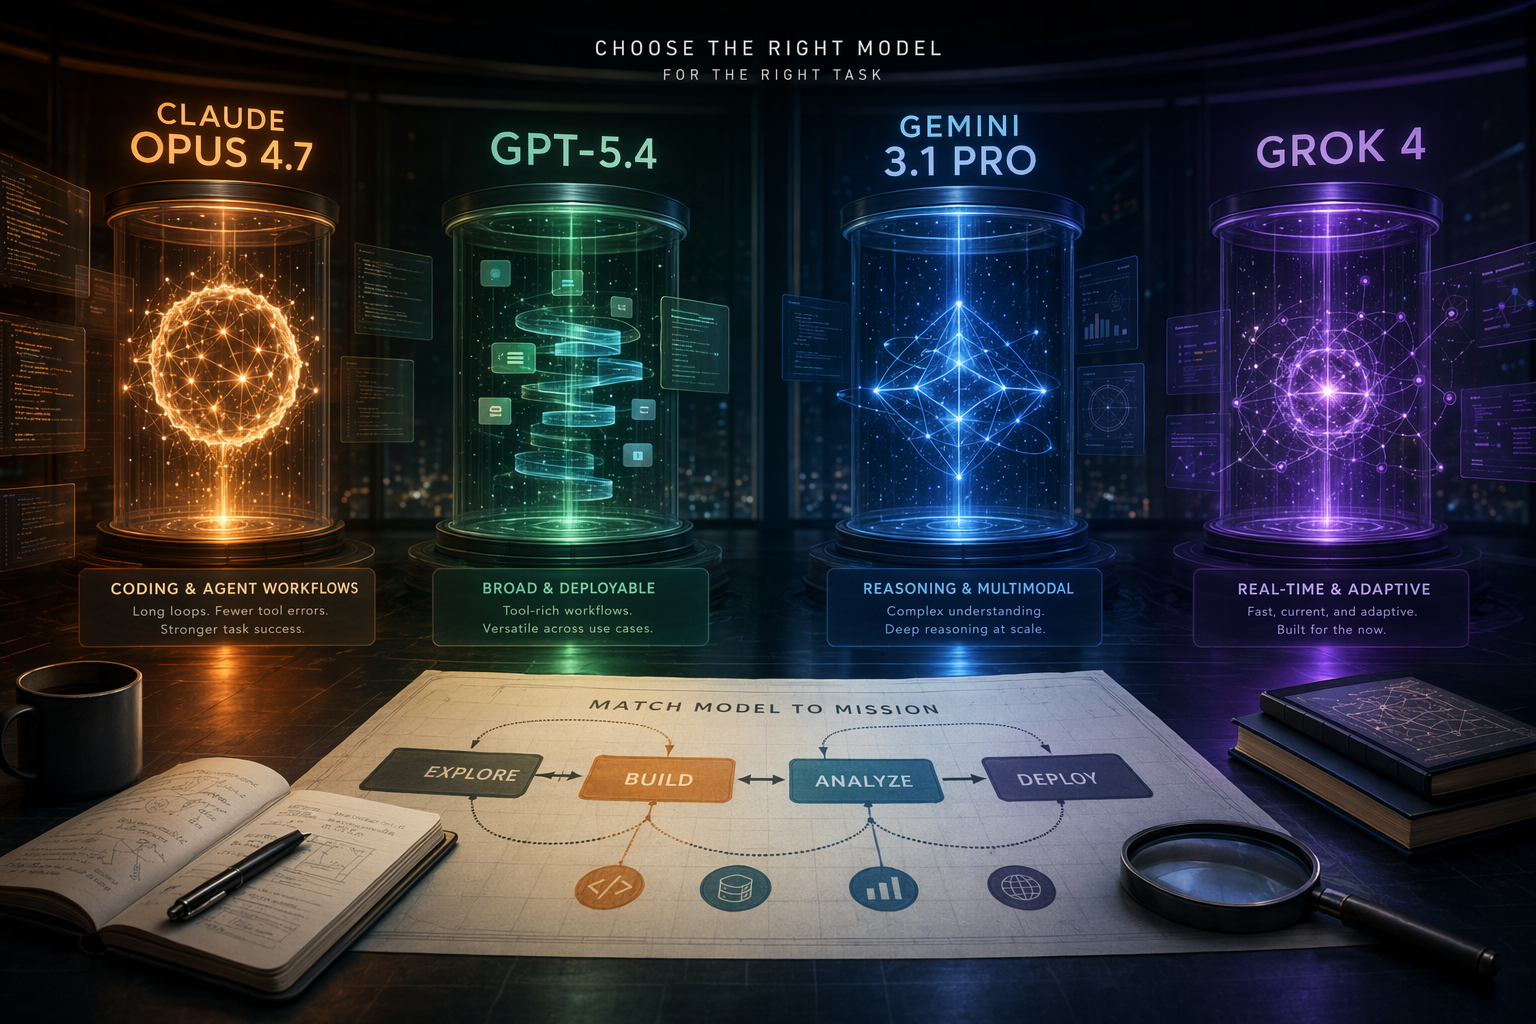
Claude Opus 4.7 vs GPT-5.4、Gemini 3.1 Pro、Grok 4:按任務選模型AI 生成的編輯用示意圖,呈現多個頂尖 AI 模型的任務型比較。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: Claude Opus 4.7 vs GPT-5.4、Gemini 3.1 Pro、Grok 4:按任務選模型. Article summary: Claude Opus 4.7 應先用在 coding 與 agent workflow:Anthropic 稱它相較 Opus 4.6 在 Factory Droids 任務成功率提升 10% 至 15%、工具錯誤更少;但這不是對 GPT 5.4、Gemini 3.1 Pro、Grok 4 的同條件頭對頭證明。[11][5]. Topic tags: ai, llm, claude, chatgpt, gemini. Reference image context from search candidates: Reference image 1: visual subject "Start with Claude Opus 4.7 for premium coding and long agent loops, GPT-5.4 for the broadest deployable tool-rich workflows, and Gemini 3.1" source context "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro: Which Model Should You Test First? | LaoZhang AI Blog" Reference image 2: visual subject "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro Benchmarks" source context "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 — I Tested Them for 48 Hours (Here’s What Actually W
openai.com
When you put Claude Opus 4.7, GPT-5.4, Gemini 3.1 Pro and Grok 4 on the same shortlist, the most useful question is not “which one wins?” It is: where does your workflow break most often?
A third-party LLM selection guide makes the key point clearly: no single model dominates every task. Different models show different strengths in coding, structured reasoning, multimodal work, scientific questions and high-difficulty reasoning benchmarks.
Quick selection guide
If your main job is…
Start by testing…
Why
Main caveat
Complex coding, agent workflows, reliable tool use
Claude Opus 4.7
Anthropic says Opus 4.7 improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors and more reliable performance; Axios also described it as a flagship upgrade with better coding and sharper vision.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "Claude Opus 4.7 vs GPT-5.4, Gemini 3.1 Pro and Grok 4"?
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond...
What are the key points to validate first?
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond... GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is positioned strongly for multimodal input, abstract reasoning and scientific benchmarks; Grok 4 stands out on the HLE hard rea...
What should I do next in practice?
Before buying or standardising on one model, test 5 to 10 real tasks and compare first pass success, tool errors, rework, latency and cost.
Claude Opus 4.7 vs GPT-5.4, Gemini 3.1 Pro and Grok 4
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond... GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is posi...
Published byEdited with GPT-5.5Images generated with GPT Image 2
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond...
GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is positioned strongly for multimodal input, abstract reasoning and scientific benchmarks; Grok 4 stands out on the HLE hard rea...
Before buying or standardising on one model, test 5 to 10 real tasks and compare first pass success, tool errors, rework, latency and cost.
Claude Opus 4.7 vs GPT-5.4、Gemini 3.1 Pro、Grok 4:按任務選模型AI 生成的編輯用示意圖,呈現多個頂尖 AI 模型的任務型比較。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: Claude Opus 4.7 vs GPT-5.4、Gemini 3.1 Pro、Grok 4:按任務選模型. Article summary: Claude Opus 4.7 應先用在 coding 與 agent workflow:Anthropic 稱它相較 Opus 4.6 在 Factory Droids 任務成功率提升 10% 至 15%、工具錯誤更少;但這不是對 GPT 5.4、Gemini 3.1 Pro、Grok 4 的同條件頭對頭證明。[11][5]. Topic tags: ai, llm, claude, chatgpt, gemini. Reference image context from search candidates: Reference image 1: visual subject "Start with Claude Opus 4.7 for premium coding and long agent loops, GPT-5.4 for the broadest deployable tool-rich workflows, and Gemini 3.1" source context "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro: Which Model Should You Test First? | LaoZhang AI Blog" Reference image 2: visual subject "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 Pro Benchmarks" source context "Claude Opus 4.7 vs GPT-5.4 vs Gemini 3.1 — I Tested Them for 48 Hours (Here’s What Actually W
openai.com
When you put Claude Opus 4.7, GPT-5.4, Gemini 3.1 Pro and Grok 4 on the same shortlist, the most useful question is not “which one wins?” It is: where does your workflow break most often?
A third-party LLM selection guide makes the key point clearly: no single model dominates every task. Different models show different strengths in coding, structured reasoning, multimodal work, scientific questions and high-difficulty reasoning benchmarks.
Quick selection guide
If your main job is…
Start by testing…
Why
Main caveat
Complex coding, agent workflows, reliable tool use
Claude Opus 4.7
Anthropic says Opus 4.7 improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors and more reliable performance; Axios also described it as a flagship upgrade with better coding and sharper vision.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "Claude Opus 4.7 vs GPT-5.4, Gemini 3.1 Pro and Grok 4"?
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond...
What are the key points to validate first?
For coding and agent workflows, Claude Opus 4.7 should be on the first shortlist: Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6, with fewer tool errors, but that is not a same cond... GPT 5.4 is worth testing first for structured reasoning and computer use; Gemini 3.1 Pro is positioned strongly for multimodal input, abstract reasoning and scientific benchmarks; Grok 4 stands out on the HLE hard rea...
What should I do next in practice?
Before buying or standardising on one model, test 5 to 10 real tasks and compare first pass success, tool errors, rework, latency and cost.
The guide says MiniMax M2.5/M2.7, GLM-5/5.1 and Kimi K2.5 now rival frontier proprietary models on SWE-bench-style tasks.
Closing the gap on SWE-bench does not mean matching closed models on API reliability, multimodality, writing, safety or product integration.
Claude Opus 4.7: strongest signal is coding and tool reliability
The clearest public signal around Claude Opus 4.7 is Anthropic’s emphasis on task success and tool reliability. Anthropic says Claude Opus 4.7 outperforms Opus 4.6 with a 10% to 15% lift in Factory Droids task success, fewer tool errors and more reliable performance.
That makes Opus 4.7 an obvious first-round candidate for software engineering and agent-style workflows. In those settings, failure is rarely just a single wrong answer. It can mean calling the wrong tool, losing track of context, editing the wrong file, breaking a test, or forcing a human to repeatedly clean up the model’s work.
Axios also described Opus 4.7 as a meaningful upgrade to Anthropic’s flagship model, highlighting better coding and sharper vision.
The cautious interpretation is important: the available evidence strongly supports Opus 4.7 as an improvement over Opus 4.6. It is not enough, by itself, to declare that Opus 4.7 universally beats GPT-5.4, Gemini 3.1 Pro or Grok 4.
GPT-5.4: test it when the workflow is procedural
If your workload involves strict rules, table-driven processes, desktop or browser operation, tool orchestration, or multi-step decisions, GPT-5.4 belongs in the first test batch.
A third-party LLM selection guide says GPT-5.4 performs strongly on structured reasoning and computer use, and lists 75% on OSWorld.
That does not mean GPT-5.4 is automatically better than Opus 4.7 for every job. A more practical reading is this: if your biggest cost comes from step-by-step process errors, workflow control mistakes or operational tasks, test GPT-5.4 and Opus 4.7 side by side.
Gemini 3.1 Pro: prioritise it for multimodal and science-heavy work
If your inputs include images, charts, screenshots, long documents, scientific questions or research-style Q&A, Gemini 3.1 Pro should be high on the shortlist.
The same third-party guide says Gemini 3.1 Pro leads on abstract reasoning, multimodal input and scientific benchmarks, and lists 94.3% on GPQA.
The point is task fit, not brand preference. If the real workflow contains a lot of visual material or scientific content, choosing only from coding leaderboards may cause you to miss Gemini 3.1 Pro’s main strengths.
Grok 4: notable for hard reasoning, but do not overgeneralise
Grok 4 is worth watching on difficult reasoning benchmarks. The third-party guide says Grok 4 leads on HLE, with a score of 50.7%.
But an HLE result should not be treated as proof that Grok 4 is the best choice for everyday business workflows, content production, coding agents or tool-heavy work. Another model-ranking article makes a useful caution: benchmarks matter, but the daily experience of building with a model is often shaped by reliability, UI capability and whether the cost lets teams iterate freely.
Why a leaderboard is not enough
There are three reasons to be careful with rankings.
First, comparison pages often combine benchmarks collected at different times. Failing Fast’s AI coding model comparison cites SWE-bench data from February 2026, Aider data from October 2025 and Arena Code data from February 2026. That kind of table can give direction, but it should not be treated as a perfect same-day, same-condition ranking of every model.
Second, official self-comparisons and third-party cross-model guides answer different questions. Anthropic’s Opus 4.7 material is strongest as evidence that Opus 4.7 improves on Opus 4.6. A third-party guide can help with cross-model selection, but it is not the same as an official joint benchmark released by OpenAI, Google, xAI and Anthropic under one shared methodology.
Third, real product experience includes factors that do not always show up in benchmark scores. One model-ranking article explicitly notes that benchmarks are useful, but day-to-day building is often dominated by reliability, UI capability and cost.
A practical test plan before rollout
If you are choosing a model for purchasing, production deployment or team-wide standardisation, do not stop at “which model is strongest?” Run a small, repeatable evaluation instead:
Pick 5 to 10 tasks your team actually performs, such as fixing a bug, adding a feature, refactoring code, reading a long document, analysing a screenshot, drafting a specification, or calling tools.
Give every model the same prompt, same background material and same success criteria.
Track first-pass success, rework, tool errors, hallucinations, latency, cost and human correction time.
Look at the worst answers, not just the best ones. In production, failure modes usually matter more than demo highlights.
If the work involves sensitive data, compliance or privacy requirements, separately check data retention, deployment options and enterprise controls.
Bottom line
Claude Opus 4.7 is a first-round candidate for coding, agent workflows and reliable tool use. Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6 and produces fewer tool errors; Axios also describes Opus 4.7 as a flagship upgrade with better coding and sharper vision.
But the evidence does not support a simple “one model rules them all” answer. The more useful conclusion from third-party selection guidance is that different top models are optimised for different failure points: GPT-5.4 for structured reasoning and computer use, Gemini 3.1 Pro for multimodal and science-heavy tasks, Grok 4 for hard reasoning benchmarks, and newer entrants such as MiniMax, GLM and Kimi for competitive SWE-bench-style performance.
The safest choice is to treat Claude Opus 4.7 as a leading candidate for coding and agent work, then test it against GPT-5.4, Gemini 3.1 Pro and Grok 4 using your own real workflow.
The guide says MiniMax M2.5/M2.7, GLM-5/5.1 and Kimi K2.5 now rival frontier proprietary models on SWE-bench-style tasks.
Closing the gap on SWE-bench does not mean matching closed models on API reliability, multimodality, writing, safety or product integration.
Claude Opus 4.7: strongest signal is coding and tool reliability
The clearest public signal around Claude Opus 4.7 is Anthropic’s emphasis on task success and tool reliability. Anthropic says Claude Opus 4.7 outperforms Opus 4.6 with a 10% to 15% lift in Factory Droids task success, fewer tool errors and more reliable performance.
That makes Opus 4.7 an obvious first-round candidate for software engineering and agent-style workflows. In those settings, failure is rarely just a single wrong answer. It can mean calling the wrong tool, losing track of context, editing the wrong file, breaking a test, or forcing a human to repeatedly clean up the model’s work.
Axios also described Opus 4.7 as a meaningful upgrade to Anthropic’s flagship model, highlighting better coding and sharper vision.
The cautious interpretation is important: the available evidence strongly supports Opus 4.7 as an improvement over Opus 4.6. It is not enough, by itself, to declare that Opus 4.7 universally beats GPT-5.4, Gemini 3.1 Pro or Grok 4.
GPT-5.4: test it when the workflow is procedural
If your workload involves strict rules, table-driven processes, desktop or browser operation, tool orchestration, or multi-step decisions, GPT-5.4 belongs in the first test batch.
A third-party LLM selection guide says GPT-5.4 performs strongly on structured reasoning and computer use, and lists 75% on OSWorld.
That does not mean GPT-5.4 is automatically better than Opus 4.7 for every job. A more practical reading is this: if your biggest cost comes from step-by-step process errors, workflow control mistakes or operational tasks, test GPT-5.4 and Opus 4.7 side by side.
Gemini 3.1 Pro: prioritise it for multimodal and science-heavy work
If your inputs include images, charts, screenshots, long documents, scientific questions or research-style Q&A, Gemini 3.1 Pro should be high on the shortlist.
The same third-party guide says Gemini 3.1 Pro leads on abstract reasoning, multimodal input and scientific benchmarks, and lists 94.3% on GPQA.
The point is task fit, not brand preference. If the real workflow contains a lot of visual material or scientific content, choosing only from coding leaderboards may cause you to miss Gemini 3.1 Pro’s main strengths.
Grok 4: notable for hard reasoning, but do not overgeneralise
Grok 4 is worth watching on difficult reasoning benchmarks. The third-party guide says Grok 4 leads on HLE, with a score of 50.7%.
But an HLE result should not be treated as proof that Grok 4 is the best choice for everyday business workflows, content production, coding agents or tool-heavy work. Another model-ranking article makes a useful caution: benchmarks matter, but the daily experience of building with a model is often shaped by reliability, UI capability and whether the cost lets teams iterate freely.
Why a leaderboard is not enough
There are three reasons to be careful with rankings.
First, comparison pages often combine benchmarks collected at different times. Failing Fast’s AI coding model comparison cites SWE-bench data from February 2026, Aider data from October 2025 and Arena Code data from February 2026. That kind of table can give direction, but it should not be treated as a perfect same-day, same-condition ranking of every model.
Second, official self-comparisons and third-party cross-model guides answer different questions. Anthropic’s Opus 4.7 material is strongest as evidence that Opus 4.7 improves on Opus 4.6. A third-party guide can help with cross-model selection, but it is not the same as an official joint benchmark released by OpenAI, Google, xAI and Anthropic under one shared methodology.
Third, real product experience includes factors that do not always show up in benchmark scores. One model-ranking article explicitly notes that benchmarks are useful, but day-to-day building is often dominated by reliability, UI capability and cost.
A practical test plan before rollout
If you are choosing a model for purchasing, production deployment or team-wide standardisation, do not stop at “which model is strongest?” Run a small, repeatable evaluation instead:
Pick 5 to 10 tasks your team actually performs, such as fixing a bug, adding a feature, refactoring code, reading a long document, analysing a screenshot, drafting a specification, or calling tools.
Give every model the same prompt, same background material and same success criteria.
Track first-pass success, rework, tool errors, hallucinations, latency, cost and human correction time.
Look at the worst answers, not just the best ones. In production, failure modes usually matter more than demo highlights.
If the work involves sensitive data, compliance or privacy requirements, separately check data retention, deployment options and enterprise controls.
Bottom line
Claude Opus 4.7 is a first-round candidate for coding, agent workflows and reliable tool use. Anthropic says it improves Factory Droids task success by 10% to 15% over Opus 4.6 and produces fewer tool errors; Axios also describes Opus 4.7 as a flagship upgrade with better coding and sharper vision.
But the evidence does not support a simple “one model rules them all” answer. The more useful conclusion from third-party selection guidance is that different top models are optimised for different failure points: GPT-5.4 for structured reasoning and computer use, Gemini 3.1 Pro for multimodal and science-heavy tasks, Grok 4 for hard reasoning benchmarks, and newer entrants such as MiniMax, GLM and Kimi for competitive SWE-bench-style performance.
The safest choice is to treat Claude Opus 4.7 as a leading candidate for coding and agent work, then test it against GPT-5.4, Gemini 3.1 Pro and Grok 4 using your own real workflow.
iternal.aiThe Definitive LLM Selection & Benchmarks Guide
anthropic.comClaude Opus 4.7 - Anthropic
axios.comAnthropic releases Claude Opus 4.7, concedes it trails ... - Axios
adam.holter.comAI Labs LLM Rankings 2026: Claude vs GPT-5 vs Gemini 3 vs Grok
failingfast.ioAI coding model comparison - Failing Fast