Trending AI Posts & Hot Research Catchup - Page 1724
Did old medical textbooks really say studying shrank the uterus?
4 sources0The sources provided do not identify a medical textbook that taught reading, studying, or education could make the uterus shrink.
GPT-5.5 vs Claude Opus 4.7: Which is better for coding?
18 sources0GPT 5.5 is the first model to try for terminal heavy coding agents: VentureBeat reports 82.7% on Terminal Bench 2.0 versus 69.4% for Claude Opus 4.7.[6]
GPT-5.5 vs Claude Opus 4.7 for coding: Claude for patches, GPT for terminal agents
19 sources0For fixing existing codebases, passing tests, and preparing PR style patches, Claude Opus 4.7 is the better first model to evaluate: reported SWE bench Pro figures put Claude Opus 4.7 at 64.3% versus GPT 5.5...
How to Use DeepSeek: Web, Mobile App, and API Setup
23 sources0The quickest non technical route is DeepSeek’s official site: Start Now opens the web experience, while the same page links to API access and the app.[24]
GPT-5.5 vs Claude Opus 4.7 vs DeepSeek V4 vs Kimi K2.6: benchmark winners by workload
24 sources0Treat the scores as use case signals, not a final league table. Public results mix reasoning settings, reporting dates, provider reported numbers and third party analysis.
How Strong Is GPT-5.5? Benchmarks Show a Top-Tier Model, Not a Clean Sweep
16 sources0GPT 5.5 is a top tier generalist, not a clean sweep: it scores 82.7 on Terminal Bench 2.0 and 51.7 on FrontierMath Tier 1–3, while Claude Opus 4.7 leads SWE Bench Pro and Gemini 3.1 Pro and Mythos Preview le...
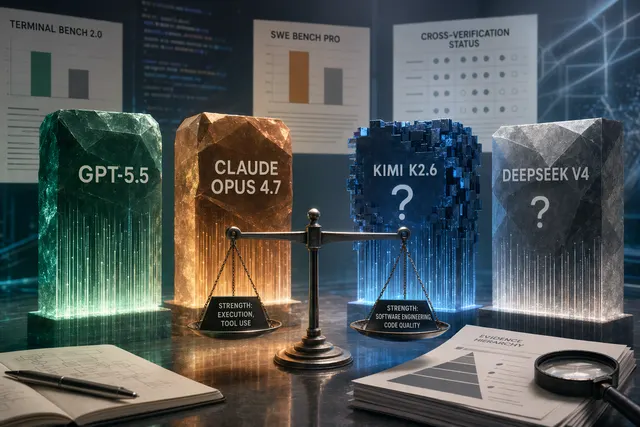
GPT-5.5 vs Claude Opus 4.7 vs Kimi K2.6 vs DeepSeek V4: benchmark comparison and evidence quality
16 sources0There is not enough consistent data to name one fair overall winner. In OpenAI’s shared table, Claude Opus 4.7 leads GPT 5.5 on SWE Bench Pro, 64.3% to 58.6%, while GPT 5.5 leads on Terminal Bench 2.0, 82.7%...
Kimi K2.6 Review: Excellent for Coding, Still Unproven as an All-Purpose AI
12 sources0Kimi K2.6 looks genuinely strong for coding: MLQ.ai reports 58.6 on SWE Bench Pro and 65.8% pass@1 on SWE bench Verified, but one review notes independent benchmark figures are still preliminary [8][9].
Kimi K2.6 vs GPT-5.5, Gemini 2.5 Pro and Claude: Developer Verdict
23 sources0Kimi K2.6 is the strongest low cost coding agent candidate in this comparison: OpenRouter lists 262,144 context tokens and $0.75/$3.50 per 1M input/output tokens, but the evidence does not prove it beats GPT...
GPT-5.5 vs. Claude Opus 4.7: Which AI Model Fits Your Work?
21 sources0If you want a model to turn limited instructions into research, analysis, code and documents, GPT 5.5 is the easier first model to test.
DeepSeek V4 early verdict: near frontier, not yet “world’s best”
18 sources0DeepSeek’s official API docs list a “DeepSeek V4 Preview Release” dated April 24, 2026, but detailed performance claims still rely heavily on external analysis and contested leaks.[13][1][8]
GPT-5.5 in Spain: how to check if your account has access
18 sources0The sources reviewed do not show a clear Spain specific block for GPT 5.5; if it is missing, the likelier explanation is rollout timing by account, plan, organisation or product channel.