Trending AI Posts & Hot Research Catchup - Page 1716
Why ChatGPT feels more emotionally attuned—but writes like customer support
20 sources0The public record supports a narrower claim: OpenAI has tuned ChatGPT toward more natural, emotionally aware and sensitive conversations, but public sources do not prove a general collapse in writing ability...
Claude Opus 4.7 for Mainland China users: availability, price and migration FAQ
15 sources0For users in or connected to Mainland China, the first question is availability and compliance, not benchmark scores.
GPT-5.5 “Spud” fact check: what can actually be verified?
18 sources0The strongest verifiable claim is narrow: named outlets have reported that OpenAI is preparing a model codenamed Spud and that pretraining reportedly finished, but the OpenAI API Models source reviewed here...
GPT Image 2 API Pricing: OpenAI’s Listed Costs and How to Estimate Usage
16 sources0OpenAI’s pricing page lists GPT image 2 at $8.00 for inputs and $2.00 for cached inputs, but the provided evidence does not verify a flat per image total; estimate costs only after confirming the live billin...
GPT-5.5 Spud Fact-Check: No Verified OpenAI API Pricing or Latency Data
24 sources0No official source in this evidence set verifies GPT 5.5 Spud as a public OpenAI API model or provides Spud pricing or latency data; OpenAI docs list GPT 5.4 as latest and show visible pricing rows for GPT 5...
Using Claude Opus 4.7 from Hong Kong: the official routes to check
22 sources0Hong Kong teams looking for an official path should first check Google Cloud Vertex AI or Amazon Bedrock, because both have official Claude Opus 4.7 documentation covering model availability and platform spe...
Will Claude Opus 4.7’s new tokenizer make prompts more expensive?
17 sources0Yes, it can: Anthropic says Claude Opus 4.7’s new tokenizer may use roughly 1x to 1.35x as many tokens when processing text compared with previous models, up to about 35% more, depending on content.[34]
Is OpenAI’s “Spud” really GPT-5.5? What the evidence shows
24 sources0There is not enough official evidence to treat “GPT 5.5 Spud” as a confirmed or available OpenAI model.
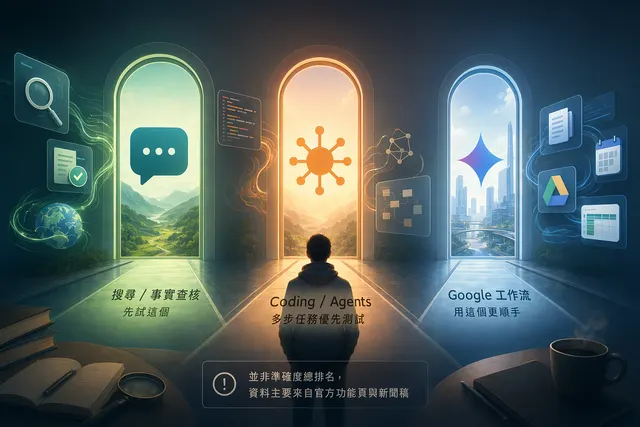
Claude Opus 4.7 vs ChatGPT vs Gemini: which AI fits search, fact-checking and coding?
21 sources0For search, research notes and fact checking drafts, ChatGPT is the best first tool to test because OpenAI lists Search across Free, Go, Plus, Pro, Business and Enterprise, and its Enterprise/Edu documentati...
GPT-5.5 Spud fact check: no official confirmation found
35 sources0No official OpenAI source in the reviewed evidence confirms a public GPT 5.5 “Spud” model or a Spud specific long context benchmark; the official materials point to GPT 5.4, so Spud reliability claims should...
Claude Opus 4.7 in Mainland China: Official Access Is Still Unsupported
17 sources0Claude Opus 4.7 has launched and appears in Anthropic’s model documentation, but mainland China is not included in the official API or Claude.ai supported region lists reviewed for this check.[12][11][21][26...
Claude Opus 4.7 vs. GPT-5.5 Spud: No Verified Hallucination Benchmark Yet
30 sources0Claude Opus 4.7 is official, but GPT 5.5 Spud is not verified in the provided official OpenAI materials, so there is no evidence backed Claude versus Spud hallucination winner.