Can You Upload That File to AI? A Privacy and Secrets Checklist
Do not paste identifiable personal data, company confidential material or unpublished government documents into an unapproved public AI tool unless data protection, retention, reuse, opt out, monitoring and incident r... The safest test is not the AI brand.
Published byEdited with GPT-5.5Images generated with GPT Image 2
Do not paste identifiable personal data, company confidential material or unpublished government documents into an unapproved public AI tool unless data protection, retention, reuse, opt out, monitoring and incident r...
The safest test is not the AI brand. Ask whether the data is sensitive, how the service handles it, whether your organisation permits the use and whether any incident can be traced and managed.
Government material should be separated into public, low sensitivity information and unpublished or sensitive files such as internal drafts, investigations or enforcement records; public sector AI examples also highli...
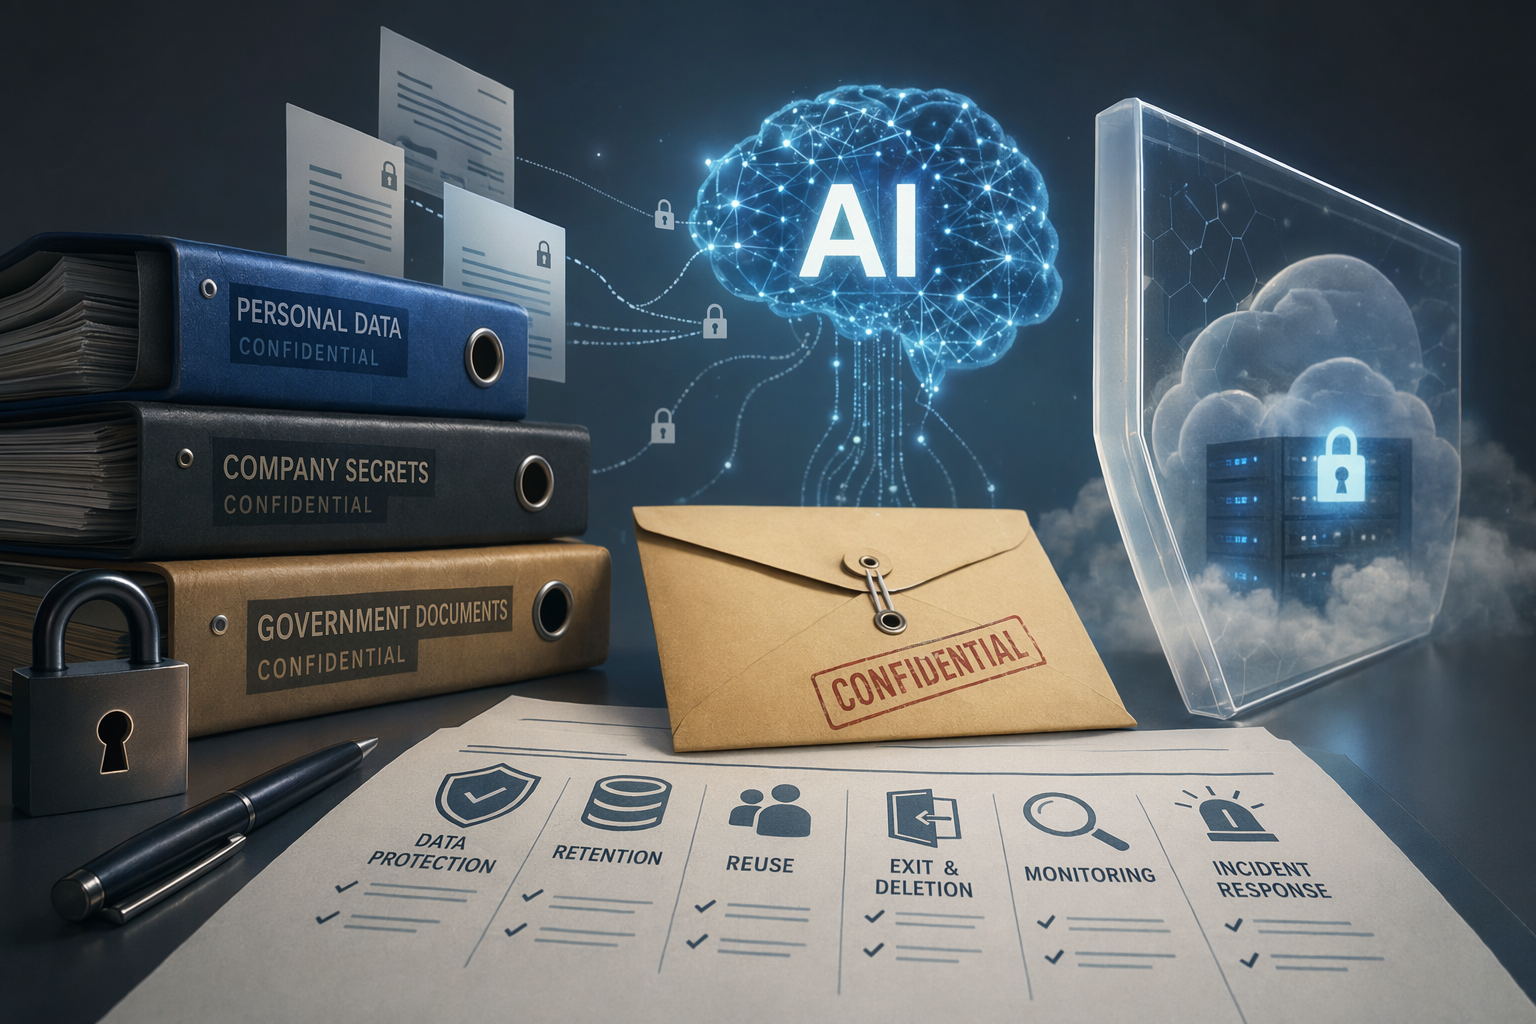
資料可以上傳到 AI 嗎?個資、公司機密與政府文件安全指南AI 生成示意圖:上傳資料前,先判斷個資、公司機密與政府文件的外流風險。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: 資料可以上傳到 AI 嗎?個資、公司機密與政府文件安全指南. Article summary: 預設不要把可識別個資、公司機密或未公開政府文件貼到一般公開型 AI;只有在資料保護、留存、再利用、退出、監控與事件回應都明確時,才考慮用受控工具處理。[1][2]. Topic tags: ai, data privacy, security, data governance, enterprise ai. Reference image context from search candidates: Reference image 1: visual subject "你公司的AI 工具,你的資料會被拿去訓練嗎?這就像把商業機密放在一個透明的信封裡。根據估計,一份有價值的商業機密,被公開可能造成數百萬到上千萬的損失。" source context "想問一下,如果是公司的隱私資料,到底該不該交由 AI 來判斷、整合、執行? 我今天跟朋友在聊,他們公司有很多機密的資料,包括客戶隱私資訊,那這些東西如果上傳到 LLM 模型會不會外洩? 坦白講,我自己是不會那麼擔心,但公司有一些規範會禁止使" Reference image 2: visual subject "第八,敏感的公司資訊。若將含有公司機密的檔案上傳至聊天機器人,可能違反僱主規定,並增加商業機密外洩的風險。 《Lifehacker》指出,用戶應假設所有輸入到" source context "AI聊天機器人潛藏隱私風險 用戶應慎防八大類個資外洩 - 科技新聞 - PChome Online 新聞" Style: premium digital editorial illustration, source-backed research mood, clean composition, high detail, modern web publication hero. Use
openai.com
Before you drop a file, table, contract, memo or block of code into an AI chatbot, do not stop at the question: is this AI safe? A better question is: what would happen if this exact text leaked, was retained, was reused or became visible to the wrong people?
Risk frameworks for generative AI do not treat data handling as an afterthought. NIST, the U.S. National Institute of Standards and Technology, lists data provenance, data protection, data retention, commercial use, opt-outs, impact assessments, incident response, monitoring and risk-based controls among governance issues for generative AI. The European Data Protection Board, or EDPB, has also focused specifically on privacy risks and mitigations for large language model systems.
In this guide, a public AI tool means a cloud AI service that has not been approved by your organisation and where you have not confirmed the rules for data retention, commercial use or further processing, opt-outs, access rights, monitoring and incident response. That does not mean AI can never process sensitive material. It means you need verifiable governance answers before the original data goes in.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "Can You Upload That File to AI? A Privacy and Secrets Checklist"?
Do not paste identifiable personal data, company confidential material or unpublished government documents into an unapproved public AI tool unless data protection, retention, reuse, opt out, monitoring and incident r...
What are the key points to validate first?
Do not paste identifiable personal data, company confidential material or unpublished government documents into an unapproved public AI tool unless data protection, retention, reuse, opt out, monitoring and incident r... The safest test is not the AI brand. Ask whether the data is sensitive, how the service handles it, whether your organisation permits the use and whether any incident can be traced and managed.
What should I do next in practice?
Government material should be separated into public, low sensitivity information and unpublished or sensitive files such as internal drafts, investigations or enforcement records; public sector AI examples also highli...
The short answer: if you cannot answer the data questions, do not upload the original
Identifiable personal data, company secrets and unpublished government documents should not be pasted directly into unapproved public AI tools. That applies even if you only want a summary, translation, rewrite or debugging help. If the input could reveal a person, customer, internal decision, credential or protected information, first remove or mask sensitive fields, turn the material into a non-identifying summary, or use an approved controlled environment.
The safer test is not the name on the AI product. It is whether four things are clear:
what kind of data you are submitting;
how the service keeps, uses or deletes it;
whether your organisation explicitly allows that use;
whether the activity can be monitored, traced and handled if something goes wrong.
NIST includes data protection, data retention, monitoring, incident response, opt-outs and risk-based controls in generative AI governance. If those points are unanswered, do not upload the original file.
Personal data, business secrets and government files: how to think about the risk
Data type
Basic rule
What to confirm before using AI
Personal data
Do not upload text that can identify a person. If use is necessary, minimise the data, mask it or de-identify it, and confirm that the service terms and your organisation’s rules allow the use.
EDPB treats LLM privacy risks and mitigations as a dedicated issue; NIST also includes data protection, data retention, impact assessments and monitoring in generative AI governance.
Company confidential information
Do not upload it to an unapproved public AI tool. Contracts, customer lists, bids, merger or acquisition material, legal files, source code, keys and credentials should be treated as high risk.
NIST’s governance topics include commercial use, data provenance, data protection, data retention, incident response, monitoring and secure software development practices.
Government documents
Separate already public, low-sensitivity and lawfully reusable information from unpublished memos, internal approvals, policy drafts, investigation files or enforcement material. The latter should not be put into a public AI tool.
The European Commission’s Joint Research Centre discusses generative AI use in the public sector, and a European Parliament annexed case summary refers to use of official Bundestag data while avoiding personal or sensitive information.
Five questions to ask before uploading anything
If you cannot answer even one of these, do not paste the original content into a public AI tool.
Does the content include personal data or sensitive information? If the material could identify someone or create a privacy risk, do not paste the original. The EDPB document is specifically concerned with privacy risks and mitigations in LLM-based systems.
Will the service retain the input or output, and for how long? NIST lists data retention as a generative AI risk-management issue.
Can the data be used commercially, further processed or used to improve the service? Is there an opt-out? NIST includes commercial use, data protection, data retention and opt-outs among governance topics.
Who can use the tool, and can use be traced? NIST refers to user credentials and qualifications, discouraging anonymous use and monitoring. In practice, an organisation needs to know who used the tool, for what purpose and with what kind of data.
Has the organisation planned for impact assessment, incident response and risk-based controls? These are also part of NIST’s generative AI risk-management guidance.
A sentence in your prompt saying “keep this confidential” is not a security control. What matters is whether the service retains the data, who can access it, whether reuse can be refused, who handles an incident and whether your organisation permits the upload.
Green, yellow and red: a practical upload guide
The following list turns data protection, retention and risk-based control principles into everyday decisions. It is not legal advice, and your own organisation’s security, privacy, legal and records-management rules should come first.
Green: usually lower risk, but still check the terms
You can consider using AI when the material is:
already public, low sensitivity and something you are allowed to use;
de-identified, stripped of sensitive fields or rewritten so it cannot reasonably point back to a person, customer, case or internal secret;
reduced to the minimum background needed for the task, rather than a full contract, government file, customer spreadsheet or codebase.
Public does not always mean risk-free. If public material still contains personal or sensitive information, treat it under privacy and data-protection rules.
Yellow: rewrite, mask or get approval first
Pause before uploading material that includes:
information about customers, employees, suppliers, case parties or members of the public;
source code, technical documentation or architecture diagrams, especially anything that may include keys, credentials or vulnerability details; NIST includes secure software development and risk-based controls in generative AI governance;
internal government documents, unpublished official correspondence, approval notes, evaluation material or cross-agency working files; public-sector generative AI use still has to manage personal and sensitive-information risks.
These materials are not necessarily impossible to process with AI. But they should not be dropped into an unapproved public tool without retention rules, monitoring, incident response and an approval path.
Red: do not upload to a public AI tool
Do not upload:
material that law or internal policy says must not be disclosed;
classified documents or material involving national security, law enforcement, investigations, procurement evaluation or other highly sensitive work;
passwords, API keys, private keys, certificates, access tokens or anything that can be used to enter a system;
data for which you cannot confirm the source, permission to use it, retention rules, deletion rules or reuse conditions.
De-identification is more than deleting names
Removing a name is not enough if other details still point to the person or case. Identification numbers, phone numbers, email addresses, addresses, account numbers, case numbers, rare job titles, or unusual combinations of dates and locations can still create privacy risk. Because LLM privacy risks and mitigations are a central concern in the EDPB material, upload preparation should remove or rewrite identifying details, linkable clues and unnecessary fields together.
Safer options include:
replacing real names and organisation names with labels such as Person A or Company B;
providing only the minimum excerpt needed;
rewriting the original file into an abstract scenario;
aggregating lists, logs or tables before sharing them;
using an approved organisational tool and process if the task genuinely requires original text.
Government documents: public data and internal files are not the same thing
Public-sector use of generative AI is not simply a yes-or-no question. The European Commission’s Joint Research Centre treats public-sector use as a specific area of discussion in its Generative AI Outlook report. A European Parliament annexed case summary also refers to use of official Bundestag data, while avoiding personal or sensitive information.
What may be suitable for AI is usually already public, low-sensitivity official information that can lawfully be reused. What needs a much more conservative approach includes unpublished correspondence, internal approvals, policy drafts, investigation material, enforcement material, procurement evaluation records and any document containing personal or sensitive information. The former still requires checking the conditions of use; the latter should not be pasted directly into a public AI service.
The simplest rule
If a leak would harm a person, an organisation, the public interest or legal compliance, do not give the original data to a public AI tool. Minimise it, mask it or summarise it first. If the original is truly necessary, use an approved controlled tool and confirm data protection, retention, access rights, monitoring and incident-response arrangements.
europarl.europa.eu[PDF] Study - The development of GenAI from a copyright perspective
edpb.europa.eu[PDF] AI Privacy Risks & Mitigations – Large Language Models (LLMs)
nvlpubs.nist.gov[PDF] Artificial Intelligence Risk Management Framework: Generative ...
publications.jrc.ec.europa.eu[PDF] Generative AI Outlook Report - JRC Publications Repository
europarl.europa.eu[XLS] Long list-Dig-tech Law-Making - European Parliament