Claude Opus 4.7 vs Opus 4.6: क्या अभी अपग्रेड करना चाहिए?
Claude Opus 4.7 को Opus 4.6 का उसी price tier वाला targeted upgrade माना जा रहा है: LLM Stats ने 16 अप्रैल 2026 release date बताई, Anthropic पेज पर claude opus 4 7 Claude API से उपलब्ध दिखता है, और public pricing summ... सबसे बड़ा फर्क advanced software engineering, long running agentic work, vision, xhigh effort और...
प्रकाशितकर्ताGPT-5.5 से संपादितGPT Image 2 से चित्र बनाए गए
Claude Opus 4.7 को Opus 4.6 का उसी price tier वाला targeted upgrade माना जा रहा है: LLM Stats ने 16 अप्रैल 2026 release date बताई, Anthropic पेज पर claude opus 4 7 Claude API से उपलब्ध दिखता है, और public pricing summ...
सबसे बड़ा फर्क advanced software engineering, long running agentic work, vision, xhigh effort और Task Budgets जैसे controls में दिखता है; LLM Stats के अनुसार SWE bench Verified पर 4.7 का score 87.6% है, जो 4.6 से 6.8...
फिर भी migration अंधाधुंध नहीं होना चाहिए: कई headline numbers Anthropic self reported benchmarks, partner internal cases या proprietary benchmarks से जुड़े हैं, इसलिए अपने production workflow पर A/B test जरूरी है।[3][6]
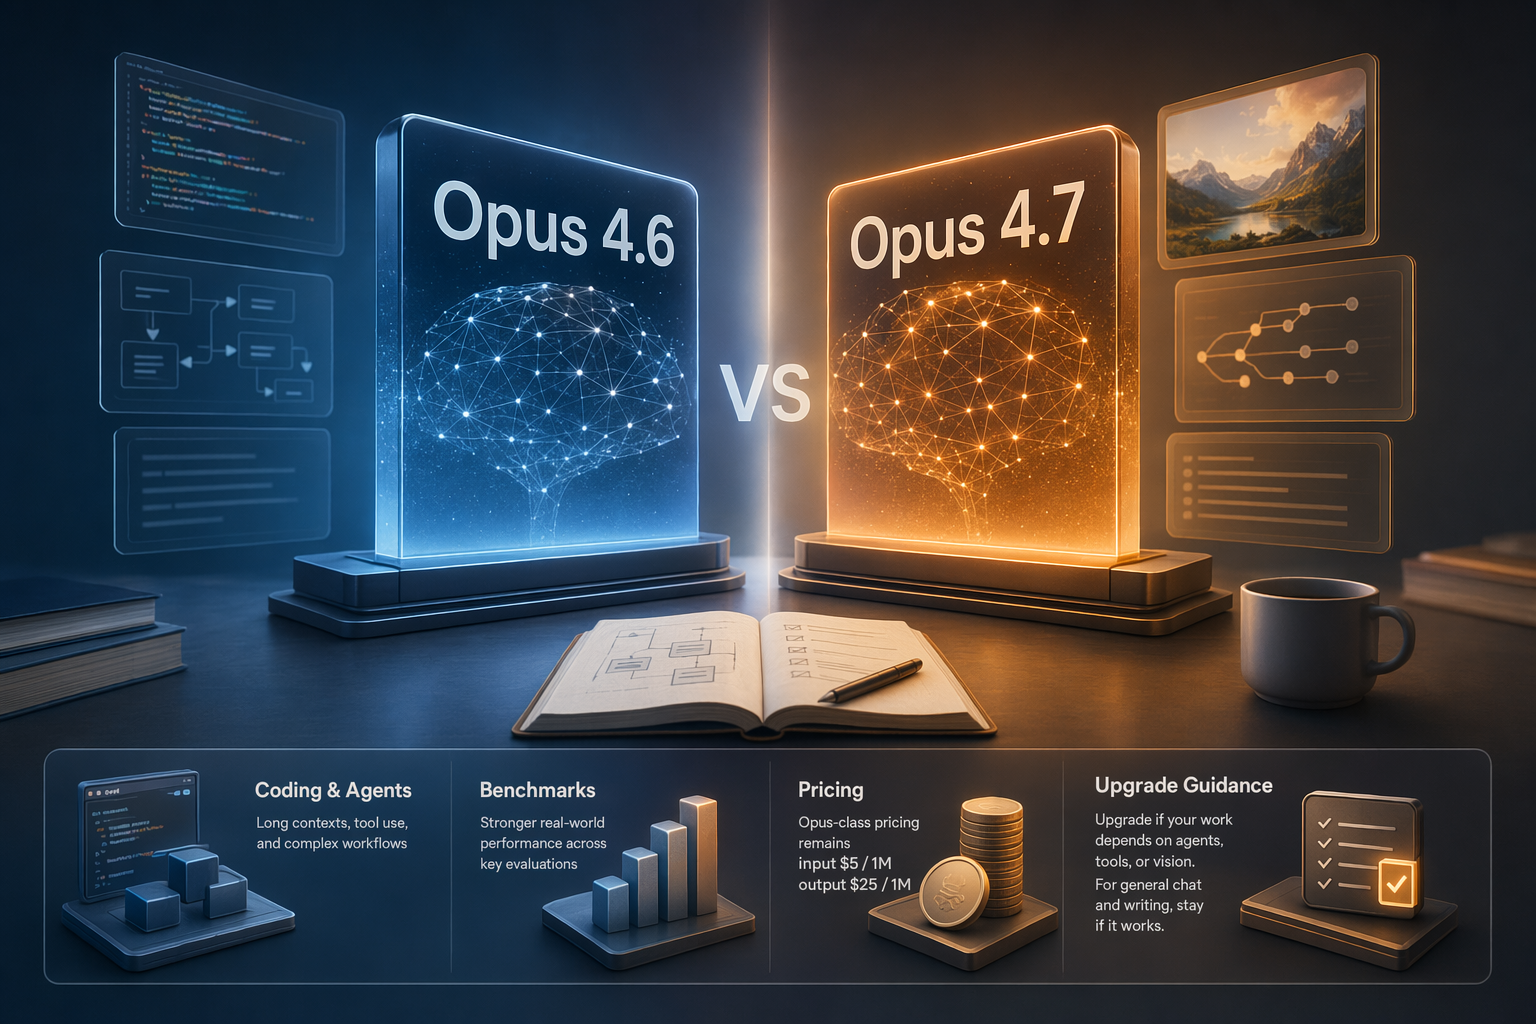
Claude Opus 4.7 vs Opus 4.6:差異、價格、Benchmark 與升級建議AI 生成的 Claude Opus 4.7 vs Opus 4.6 比較主視覺。
AI संकेत
Create a landscape editorial hero image for this Studio Global article: Claude Opus 4.7 vs Opus 4.6:差異、價格、Benchmark 與升級建議. Article summary: Claude Opus 4.7 在 2026 04 16 上線,公開資料顯示 Opus 級價格仍是每百萬 input $5、output $25;若你做 coding agent、長流程工具調用或視覺理解,值得優先試升,但一般聊天或文案不必只為版本號遷移。[6][8][9]. Topic tags: ai, anthropic, claude, llm, ai agents. Reference image context from search candidates: Reference image 1: visual subject "# Claude Opus 4.7 vs Claude Opus 4.6 in 2026: Should You Upgrade Now? A route-first upgrade guide that compares Claude Opus 4.7 and Claude Opus 4.6 through workflow fit, benchmark" source context "Claude Opus 4.7 vs Claude Opus 4.6 in 2026: Should You Upgrade ..." Reference image 2: visual subject "# Claude Opus 4.7 vs Opus 4.6. Head-to-head comparison of Claude Opus 4.7 vs Opus 4.6: benchmark deltas, pricing, effort levels, vision, tokenizer, and a migration checklist. Opus" source
openai.com
छोटा जवाब: Claude Opus 4.7 को Opus 4.6 का ऐसा upgrade समझिए जो हर casual chat user के लिए तुरंत जरूरी नहीं, बल्कि engineering, agent और vision workloads के लिए ज्यादा काम का है। अगर आपकी टीम Opus 4.6 से coding, repository analysis, multi-step tool calls या image understanding चला रही है, तो 4.7 को जल्द A/B test में डालना समझदारी होगी। लेकिन अगर उपयोग मुख्य रूप से सामान्य chat, summary, translation या copywriting है, तो public evidence अभी इतना नहीं है कि बिना टेस्ट पूरे workflow को बदल दिया जाए।
Studio Global AI
अपना शोध जारी रखें
इस पृष्ठ में एक स्रोत-समर्थित उत्तर शामिल है जिसे आप Studio Global के अंदर जारी रख सकते हैं।
"Claude Opus 4.7 vs Opus 4.6: क्या अभी अपग्रेड करना चाहिए?" का संक्षिप्त उत्तर क्या है?
Claude Opus 4.7 को Opus 4.6 का उसी price tier वाला targeted upgrade माना जा रहा है: LLM Stats ने 16 अप्रैल 2026 release date बताई, Anthropic पेज पर claude opus 4 7 Claude API से उपलब्ध दिखता है, और public pricing summ...
सबसे पहले सत्यापित करने योग्य मुख्य बिंदु क्या हैं?
Claude Opus 4.7 को Opus 4.6 का उसी price tier वाला targeted upgrade माना जा रहा है: LLM Stats ने 16 अप्रैल 2026 release date बताई, Anthropic पेज पर claude opus 4 7 Claude API से उपलब्ध दिखता है, और public pricing summ... सबसे बड़ा फर्क advanced software engineering, long running agentic work, vision, xhigh effort और Task Budgets जैसे controls में दिखता है; LLM Stats के अनुसार SWE bench Verified पर 4.7 का score 87.6% है, जो 4.6 से 6.8...
मुझे अभ्यास में आगे क्या करना चाहिए?
फिर भी migration अंधाधुंध नहीं होना चाहिए: कई headline numbers Anthropic self reported benchmarks, partner internal cases या proprietary benchmarks से जुड़े हैं, इसलिए अपने production workflow पर A/B test जरूरी है।[3][6]
LLM Stats ने Opus 4.7 की release date 16 अप्रैल 2026 बताई है; Anthropic पेज के अनुसार developers claude-opus-4-7 को Claude API के जरिए इस्तेमाल कर सकते हैं।
अब इसे production जैसे real tests में शामिल किया जा सकता है; यह सिर्फ teaser या waitlist वाली चीज नहीं है।
price
LLM Stats के अनुसार Opus 4.7, Opus 4.6 का direct upgrade है और कीमत input tokens के लिए $5 प्रति मिलियन तथा output tokens के लिए $25 प्रति मिलियन रहती है।
token की unit price बढ़े बिना test करना आसान है; लेकिन final bill output length, retries और workflow design पर निर्भर रहेगा।
coding और software engineering
Anthropic ने 4.7 को advanced software engineering, खासकर कठिन tasks में 4.6 से बेहतर बताया है; LLM Stats के अनुसार SWE-bench Verified पर 4.7 का score 87.6% है, जो 4.6 से 6.8 percentage points ज्यादा है।
बड़े code changes, bug fixing, repo-level reasoning, test repair और coding agents के लिए इसे पहले test करें।
लंबे agent workflows
LLM Stats के मुताबिक 4.7 में long-running agentic work के लिए self-verification से जुड़े सुधार हैं; Anthropic भी long-running tasks को improvement area के रूप में रखता है।
vision यानी image understanding
Anthropic ने 4.7 की vision capability को बेहतर बताया है और कहा है कि यह higher-resolution images संभाल सकता है; LLM Stats ने image resolution support को करीब 3.3× बताया है।
नए controls
third-party summaries में 4.7 के लिए नया xhigh effort और Task Budgets जैसे agent/coding-oriented controls बताए गए हैं।
Benchmarks क्या कहते हैं — और क्या नहीं कहते
Public benchmarks एक साफ दिशा दिखाते हैं: Opus 4.7 की ताकत मुश्किल coding, agentic workflows और vision में ज्यादा केंद्रित है। LLM Stats के अनुसार Opus 4.7 ने SWE-bench Verified पर 87.6% score किया, 4.6 से 6.8 percentage points ऊपर रहा, और 14 reported benchmarks में से 12 में 4.6 से आगे बताया गया।
लेकिन इन numbers को अंतिम सत्य की तरह पढ़ना ठीक नहीं होगा। LLM Stats खुद बताता है कि संबंधित benchmarks Anthropic self-reported हैं; Verdent AI ने भी ध्यान दिलाया है कि Anthropic release में दिए Notion और Rakuten examples, क्रमशः partner-internal context या proprietary benchmark से जुड़े हैं, कोई public standardized controlled experiment नहीं।
इसलिए benchmark से यह निष्कर्ष मजबूत होता है कि 4.7 कठिन coding, long-running agents और high-resolution vision tasks में बेहतर candidate है। पर इससे यह साबित नहीं होता कि आपकी हर Opus 4.6 production prompt chain अपने-आप बेहतर हो जाएगी। असली फायदा आपकी prompts, tools, data format, latency target और failure cost पर निर्भर करेगा।
Price: token rate वही है, total cost फिर भी बदल सकती है
Public summaries के मुताबिक Opus 4.7 और Opus 4.6 की Opus-tier unit pricing समान है: $5 प्रति मिलियन input tokens और $25 प्रति मिलियन output tokens। इससे experiment करने की barrier कम होती है, क्योंकि upgrade test शुरू करने से पहले आपको higher token price स्वीकार नहीं करना पड़ता।
फिर भी cost estimate अपने production logs से ही निकालें। अगर model लंबा output देने लगे, retries कम या ज्यादा हों, या आप xhigh effort और agent controls का इस्तेमाल शुरू करें, तो total bill 4.6 से अलग हो सकता है। उल्टा, अगर 4.7 manual correction, tool errors या failed attempts घटा दे, तो task-level cost कम भी हो सकती है। इसलिए केवल token price नहीं, बल्कि same task complete करने की total cost देखें।
किसे पहले upgrade test करना चाहिए?
इन users और teams के लिए Opus 4.7 को जल्दी test करना ज्यादा मायने रखता है:
Coding agents और software engineering teams: अगर आप Opus 4.6 से repo analysis, bug fixing, test repair, multi-file refactoring या code review कराते हैं, तो 4.7 के public improvements ठीक इन्हीं advanced software engineering और difficult coding tasks पर केंद्रित हैं।
Long-running tool workflows: अगर आपका AI agent कई rounds में planning, tool calling, debugging और self-correction करता है, तो 4.7 में long-running agentic work से जुड़े improvements test करने लायक हैं।
Vision-heavy product या operations flows: UI screenshots, tables, scanned documents, technical diagrams या design files को model से समझवाते हैं तो 4.7 की higher-resolution vision capability ज्यादा useful हो सकती है।
जो teams पहले से Opus-tier price दे रही हैं: public summary में 4.7 और 4.6 की unit price समान बताई गई है, इसलिए upgrade experiment का pricing barrier अपेक्षाकृत कम है।
कौन अभी इंतजार कर सकता है?
अगर आपका मुख्य उपयोग सामान्य chat, summary, translation, copy polishing या lightweight knowledge Q&A है, तो सिर्फ version number देखकर migration करने की जरूरत नहीं। अभी public evidence का वजन coding, agent और vision workloads पर ज्यादा है; सामान्य content tasks में उतना ही बड़ा visible improvement मिलेगा, यह कहना जल्दबाजी होगी।
दूसरी स्थिति: अगर आपकी production prompts Opus 4.6 के लिए बहुत fine-tuned हैं और fixed format, tone consistency या edge-case stability आपके लिए critical है, तो भी सावधानी बेहतर है। मजबूत model भी output style और error distribution बदल सकता है। ऐसे workflows में पहले low-traffic gray release करें, फिर coverage बढ़ाएं।
Upgrade से पहले A/B test checklist
पूरे system को एक झटके में बदलने के बजाय अपनी वास्तविक Opus 4.6 tasks पर 4.7 को साथ-साथ चलाकर देखें:
Representative tasks चुनें: सामान्य successful cases, 4.6 के frequent failure cases, long-running flows और high-value production cases सभी शामिल करें।
Prompt और tool environment fixed रखें: model version के अलावा बाकी settings समान रखें, ताकि prompt बदलाव को model improvement न समझ लिया जाए।
Results को measure करें: task success rate, manual correction time, tool errors, input/output tokens, retry count और latency record करें।
xhigh effort अलग से test करें: xhigh 4.7 से जुड़े नए controls में बताया गया है, लेकिन यह हर task के लिए बेहतर होगा ही, ऐसा मानकर न चलें। इसे normal setting से अलग compare करें।
Vision tasks को अलग benchmark करें: अगर image understanding जरूरी है, तो real screenshots, technical diagrams, tables या scanned documents से test करें, सिर्फ simple demo images से नहीं।
Opus 4.6 fallback रखें: production migration में पहले छोटा traffic share दें। quality, cost और latency stable दिखने पर ही rollout बढ़ाएं।
अंतिम सलाह
Engineering, agent और vision workloads के लिए Claude Opus 4.7 high-priority upgrade candidate है; same unit pricing इसे test करने के पक्ष में जाती है। सामान्य chat, summary और content generation users के लिए 4.7 शायद उपयोगी हो, लेकिन अभी public evidence इतना मजबूत नहीं कि सिर्फ version number के आधार पर तुरंत migration कर दिया जाए।
सबसे सुरक्षित तरीका यही है: Opus 4.7 को Opus 4.6 का serious A/B-test upgrade मानें, blind replacement नहीं। अपने real tasks पर success rate, format stability, cost और latency नापें—फिर तय करें कि full switch करना है या 4.6 fallback के साथ धीरे-धीरे आगे बढ़ना है।
verdent.aiClaude Opus 4.7 vs 4.6: Agentic Coding Comparison - Verdent AI
llm-stats.comClaude Opus 4.7 vs Opus 4.6 - LLM Stats
anthropic.comIntroducing Claude Opus 4.7 - Anthropic
help.apiyi.comClaude Opus 4.7 VS 4.6 Comprehensive Comparison