AnswersPublished16 sources
Puffin-World: An Open 3D World Model Grounded in Gravity, Geometry and Appearance
Puffin World is an open, camera centric world model that jointly represents gravity aware physics, dense depth and RGB appearance rather than predicting video pixels alone. The release includes code, three checkpoints and the Puffin 16M dataset, comprising roughly 15 million vision language camera triplets and 1 mil...
Published byEdited with GPT-5.6 TerraImages generated with GPT Image 2
Research answer
Key takeaways
- Puffin World is an open, camera centric world model that jointly represents gravity aware physics, dense depth and RGB appearance rather than predicting video pixels alone.
- The release includes code, three checkpoints and the Puffin 16M dataset, comprising roughly 15 million vision language camera triplets and 1 million challenging trajectories.
- Its benchmark figures are author reported: on Stanford2D3D, Puffin World reports median errors of 0.29° roll, 0.53° pitch and 1.62° vertical field of view.
AI Prompt
openai.comCreate a landscape editorial hero image for this Studio Global article: What is Puffin-World, the open-source multimodal world model developed by ACE Robotics, NTU S-Lab, Beijing Jiaotong University, and the Univ. Article summary: Puffin-World is an open-source, camera-centric multimodal world model that treats a world not merely as RGB video, but as three jointly modeled native states: gravity-aware physics, dense 3D geometry, and visual appearan. Topic tags: general, academic, general web. Style: premium digital editorial illustration, source-backed research mood, clean composition, high detail, modern web publication hero. Use reference image context only for broad subject, composition, and topical grounding; do not copy the exact image. Avoid: logos, brand marks, copyrighted characters, real person likenesses, fake screenshots, UI text, readable text, watermarks, charts with fake num
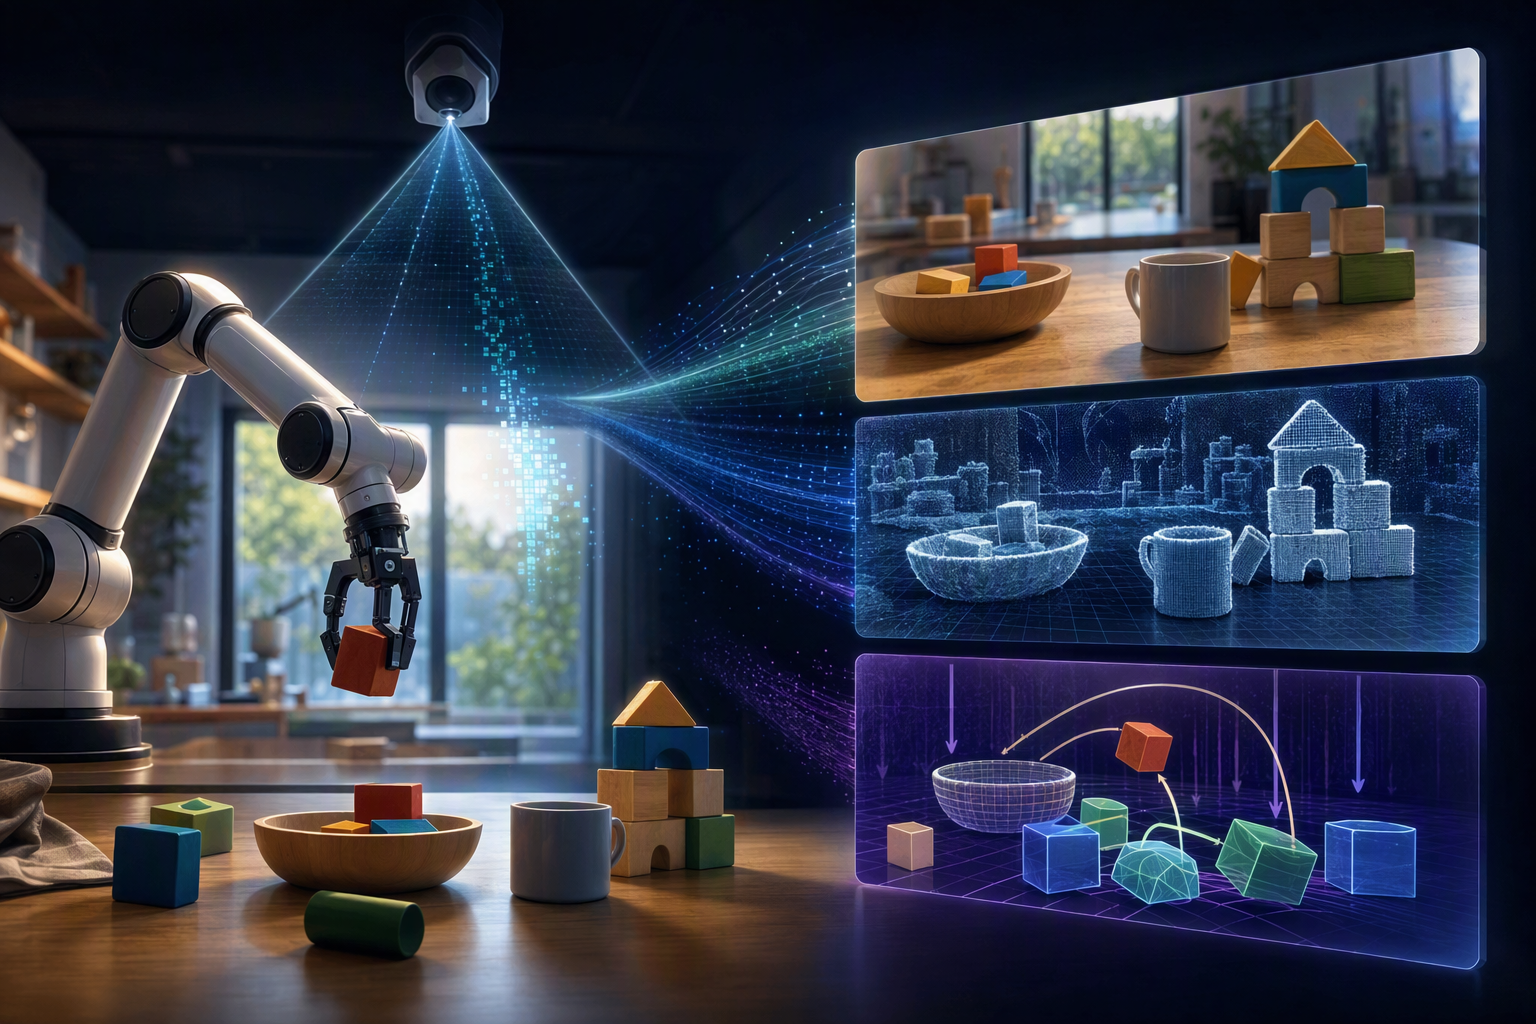
Puffin-World is an open-source multimodal world model from researchers affiliated with ACE Robotics, NTU’s S-Lab, Beijing Jiaotong University and the University of Michigan. Its central idea is to model a 3D world through three connected states—physics, geometry and appearance—so that an AI system can reason about camera orientation, generate controlled new views and reconstruct RGB-D scenes within one framework. 1
5
The core idea: more than RGB video
Many generative systems can produce plausible images, but a convincing image does not necessarily preserve a stable horizon, camera pose or 3D structure as the viewpoint changes. Puffin-World explicitly represents:
This makes it a camera-centric world model: the model is asked not only what a scene looks like, but also how a camera is oriented in relation to gravity and how that camera could move through the scene.
How the 9-channel Omni-Camera representation works
Puffin-World’s key conditioning representation is called Omni-Camera. It combines a gravity-aware absolute perspective field with ray-based relative geometry in a 9-channel dense camera condition. In practical terms, the two pieces serve different jobs: 5
- The absolute perspective field anchors the camera to a physical frame, including its orientation relative to gravity.
- The relative geometry encodes camera rotation, translation, intrinsics and compound motion between viewpoints.
The model propagates gravity inferred from a reference view along a requested trajectory. The stated purpose is to keep generated observations in a consistent physical frame and reduce the gravity or horizon drift that can appear when viewpoints are generated sequentially. 5
6
What Puffin-World can do
The project presents one framework for several previously separated tasks.
Infer camera pose from a single image
Given one image, the understanding branch predicts absolute roll, pitch and vertical field of view (FoV). Those estimates can be converted into the gravity and perspective fields used by the model’s camera representation. 5
Generate controlled free-viewpoint trajectories
Puffin-World can generate views from text plus camera controls, or from an input image plus a specified camera trajectory. Its controls cover changes in orientation, translation, intrinsics and compound motion, including roll, pitch and yaw. 5
Produce RGB-D views and reconstruct a scene
Rather than generating color alone, the model jointly produces RGB and depth along a trajectory. Those RGB-D outputs can then be consolidated into a colored 3D point cloud, without delegating reconstruction to a separate offline geometry pipeline. 5
Support closed-loop exploration
The public release includes mimic-exploration and self-calibration demonstrations. The documentation describes the gravity-aware frame as a way to re-anchor generated trajectories and limit accumulated pose inconsistency. However, the provided public materials do not fully specify the drift-correction algorithm, so this should be understood as a demonstrated capability rather than a complete account of its control loop. 5
6
Architecture: understanding plus diffusion generation
Puffin-World combines a geometry-aligned C-RADIO vision encoder, a Qwen language model, an SD3.5 diffusion generator and a lightweight connector. The design separates autoregressive camera and physical understanding from diffusion-based multi-view RGB-D generation, while keeping both in a unified system. 5
The release lists three checkpoints:
- Puffin-World-Base: Qwen2.5-7B, C-RADIOv3-H and SD3.5-medium;
- Puffin-World-Pro: Qwen2.5-1.5B, C-RADIOv4-H and SD3.5-large; and
- Puffin-World-Caption: Qwen3.5-0.8B and C-RADIOv3-H, focused on physical-caption and camera understanding.
5
Code, training and evaluation guidance, dataset-construction documentation, models and datasets are included in the public release. 5
Puffin-16M: camera-aware data at scale
Puffin-16M is described as approximately 16.5 million samples across two complementary components. 14
Puffin-Cam-15M contains about 15 million vision-language-camera triplets rendered from roughly 900,000 panoramas. Its reported camera range spans roll and pitch from −45° to +45°, with vertical FoV from 20° to 105°. 5
Puffin-Traj-1M adds 1 million challenging camera trajectories. Available project materials identify long trajectories, extreme rotations and compound actions, including pitch, yaw and roll, but do not provide a reliable numeric breakdown by motion class. 5
11
The supplied materials support coverage across indoor, outdoor, real and synthetic imagery, but they do not establish a precise scene-category distribution. 7
A large camera-pose annotation effort
The team also used Puffin-World to add absolute roll, pitch and vertical-FoV estimates to 28 public datasets—22 single-image datasets and six sequential or 3D datasets—producing roughly 44.5 million camera annotations. The paper reports that these annotations reveal common level-camera bias, generally downward-looking pitch and substantial FoV variation across datasets. 1
That annotation work matters because world models need both scene content and camera context. Relative motion alone cannot fully specify how a camera is oriented relative to gravity or a shared world frame.
Reported benchmark results
The project reports the best median error in all 12 comparisons across Stanford2D3D, MegaDepth, TartanAir and LaMAR, as well as the best AUC in 33 of 36 reported metrics when ties are included. These are results reported by the authors and have not been independently reproduced in the supplied sources. 5
Selected reported figures include:
- Stanford2D3D: 0.29° median roll error, 0.53° pitch error and 1.62° vertical-FoV error.
1
- Roll error: 0.28° on MegaDepth, 0.31° on TartanAir and 0.26° on LaMAR.
- RealEstate10K world modeling: 17.22 PSNR and 0.318 LPIPS.
- Gravity-propagation ablation: PSNR rose from 19.87 to 20.54, while LPIPS fell from 0.23 to 0.21; reported roll and pitch errors also improved.
- Challenging trajectory benchmark: 0.80° median roll error and 1.10° median pitch error.
The release also reports strong camera-control results on its Puffin-Cam-Bench, including low errors for up-vector, latitude and gravity. A separate project summary gives a 1.32° gravity-error figure, while the README reports a different gravity metric; the available sources do not make the evaluation definitions clear enough to treat those values as directly comparable. 4
5
Where the model’s limits are
Puffin-World’s “physics” representation is principally gravity and latitude, not a complete physical simulator. The release is focused mainly on static scenes and does not claim full modeling of object interactions, moving environments or long-horizon dynamics. 5
That limitation is important: Puffin-World is best understood as a substantial step toward spatially and physically grounded visual world modeling—not yet a general-purpose simulator of every changing physical process.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
People also ask
What is the short answer to "Puffin-World: An Open 3D World Model Grounded in Gravity, Geometry and Appearance"?
Puffin World is an open, camera centric world model that jointly represents gravity aware physics, dense depth and RGB appearance rather than predicting video pixels alone.
What are the key points to validate first?
Puffin World is an open, camera centric world model that jointly represents gravity aware physics, dense depth and RGB appearance rather than predicting video pixels alone. The release includes code, three checkpoints and the Puffin 16M dataset, comprising roughly 15 million vision language camera triplets and 1 million challenging trajectories.
What should I do next in practice?
Its benchmark figures are author reported: on Stanford2D3D, Puffin World reports median errors of 0.29° roll, 0.53° pitch and 1.62° vertical field of view.
Sources
kangliao929.github.ioPuffin-World · Scaling with Native 3D World States