AnswersPublished26 sources
Samsung zHBM: Direct-Stacked AI Memory Explained
Samsung says zHBM could raise AI response speed by more than 10× by stacking HBM directly on an AI accelerator rather than beside it. The company projects a zHBM enabled interface could deliver about 8× HBM5 performance, more than 10× memory density, 3× energy efficiency, and over 50% lower thermal resistance than c...
Published byEdited with GPT-5.6 TerraImages generated with GPT Image 2
Research answer
Key takeaways
- Samsung says zHBM could raise AI response speed by more than 10× by stacking HBM directly on an AI accelerator rather than beside it.
- The company projects a zHBM enabled interface could deliver about 8× HBM5 performance, more than 10× memory density, 3× energy efficiency, and over 50% lower thermal resistance than conventional HBM5.
- At the same summit, OpenAI and Intel engineers argued that CXL is better suited to supplemental capacity and colder data than to replacing HBM for active AI model execution.
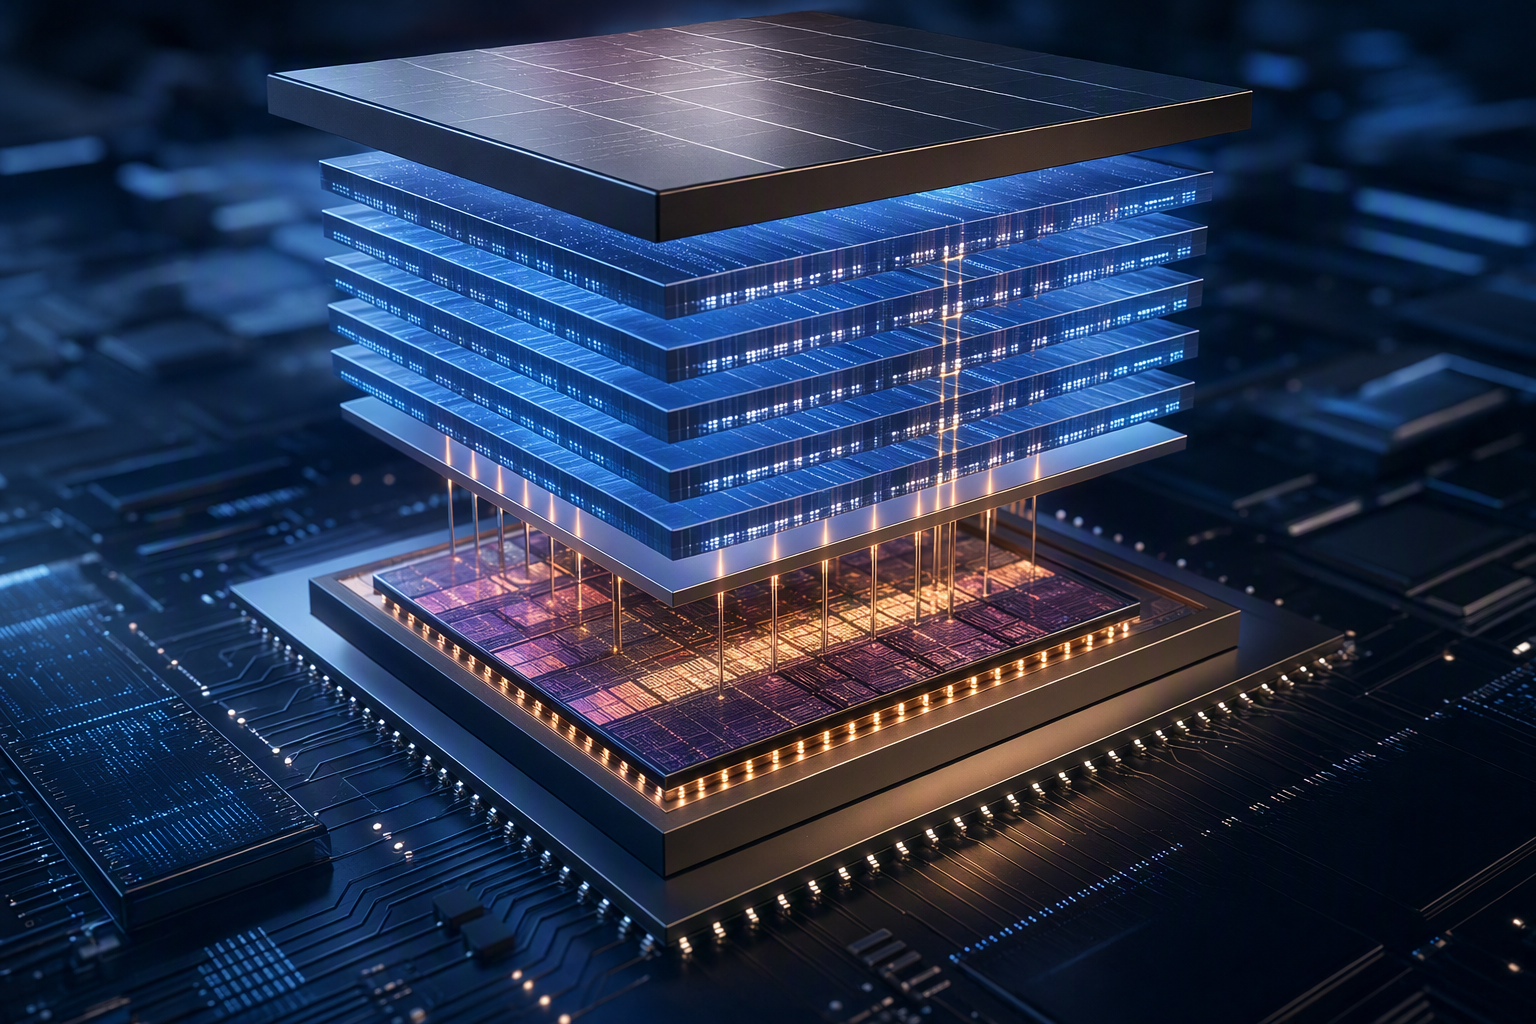
AI Prompt
openai.comCreate a landscape editorial hero image for this Studio Global article: What did Samsung Electronics reveal at the September 16, 2026, AI Infrastructure Summit about its next-generation zHBM 3D memory architectur. Article summary: Samsung presented zHBM as a longer-term “zero-distance” HBM architecture: rather than placing HBM beside an AI accelerator on a silicon interposer, as in current 2.5D packages, it would bond HBM directly above the accele. Topic tags: general, general web, user generated, news. Style: premium digital editorial illustration, source-backed research mood, clean composition, high detail, modern web publication hero. Use reference image context only for broad subject, composition, and topical grounding; do not copy the exact image. Avoid: logos, brand marks, copyrighted characters, real person likenesses, fake screenshots, UI text, readable text, watermarks, charts w
Samsung’s zHBM is a proposal to shrink the physical gap between AI compute and its highest-speed memory. Instead of putting high-bandwidth memory (HBM) next to a GPU or other accelerator, Samsung would place it directly above the processor in a vertically integrated 3D package. At the September 16 AI Infrastructure Summit in Santa Clara, Samsung framed that approach as a route to more responsive agentic AI systems. 1
9
What changes from today’s 2.5D HBM packages?
Conventional HBM is generally arranged alongside the accelerator on the same plane, with the components linked through advanced packaging. Samsung’s zHBM concept instead vertically stacks HBM directly above the AI accelerator. That is why Samsung describes it as bringing logic and memory closer together in 3D. 12
13
The intended advantage is straightforward: a shorter physical data path should improve bandwidth and power efficiency while allowing more memory capacity in a given footprint. Samsung says its design depends on next-generation wafer bonding, including hybrid copper bonding, to make the vertical integration possible. 7
48
This is an architectural concept, not a replacement for every existing HBM package today. Samsung unveiled zHBM as a concept model and has not provided a commercialization timetable. 13
14
Samsung’s performance and efficiency claims
Samsung’s targets for a next-generation interface using zHBM are ambitious:
- Approximately 8× the performance of HBM5
- More than 10× the memory density of conventional HBM5
- About 3× energy efficiency
- More than 50% lower thermal resistance
13
48
At the AI Infrastructure Summit, Samsung also said zHBM could increase AI-system response speed by more than tenfold, with a stated ambition of reaching 1,000 tokens per second. 1
9
Those numbers should be read as company projections for a future architecture, rather than independently validated benchmarks from a commercially available accelerator. The technical challenge is significant: stacking memory directly over logic must work at production yield, manage heat, and be qualified with accelerator partners.
Why it matters for agent-based AI
Samsung presented zHBM in the context of AI agents, which must repeatedly access context, run inference, use tools, and produce output. In such workloads, simply adding compute does not eliminate delays if the accelerator is waiting on data movement.
zHBM is designed to attack that memory-and-data-transfer bottleneck. The premise is that bringing HBM closer to the accelerator can help make the AI system more responsive while improving the power efficiency of moving data. 1
7 Whether that translates into the advertised end-to-end response gains will depend on the full accelerator, software, model, and packaging design—not memory placement alone.
zNAND-O is Samsung’s complementary capacity tier
Samsung paired zHBM with zNAND-O, a high-performance NAND architecture aimed at data-intensive and edge-AI environments. zNAND-O is positioned between DRAM and conventional NAND storage: it is designed to offer greater density than DRAM while improving I/O performance, latency, and power efficiency relative to conventional NAND. 49
51
The two products address different parts of the memory hierarchy:
- zHBM is intended for the fastest, accelerator-adjacent memory tier.
- zNAND-O is intended to provide a denser tier for data and model capacity that would be expensive to hold entirely in DRAM.
49
53
Samsung cited a test involving a 120-billion-parameter GPT model in which zNAND-O achieved the same tokens-per-second rate as a conventional DRAM server at one-sixth of the operating cost. That is a Samsung-reported test result, not a general cost guarantee for large-model deployments. 54
55
Samsung has also linked zNAND-O to the longer-term challenge of running very large on-device models, saying trillion-parameter-scale on-device AI could become relevant by 2030. 53
CXL is unlikely to displace HBM for active AI execution
The AI Infrastructure Summit also highlighted a key distinction in the AI memory market: more capacity is useful, but it does not make all memory interchangeable.
OpenAI accelerator researcher Daniel Morris said he had not found a CXL use case for actually running AI models, though he identified potential value for infrequently used data in large models. Intel’s Vidia Thiagarajan similarly described CXL memory pooling as a complement to secondary storage rather than a replacement for HBM, citing the bandwidth gap between CXL-connected memory and HBM. 18
22
That does not mean CXL has no role. It means the emerging architecture is more likely to be tiered: HBM close to the accelerator for bandwidth-sensitive active computation, with CXL and other storage or memory tiers serving capacity-oriented roles.
What this means for Samsung and SK hynix
The near-term HBM contest is still determined by a supplier’s ability to manufacture, qualify, and ship memory for specific accelerator platforms. zHBM gives Samsung a differentiated long-range architecture to pursue, but it does not erase the need to prove yields, thermal behavior, reliability, and customer integration.
For the broader HBM market, skepticism that CXL can replace local HBM in active model execution reinforces the importance of accelerator-adjacent high-bandwidth memory. The competitive question is therefore not only who has the most aggressive 3D-memory concept, but who can convert advanced packaging and memory designs into qualified volume products first. 18
33
36
The bottom line
Samsung’s September summit message was that AI performance is increasingly limited by memory movement, capacity, power, and heat—not just compute throughput. zHBM proposes a direct 3D memory-on-accelerator design to tackle those constraints, while zNAND-O would add a denser adjacent tier for larger AI workloads.
The potential gains Samsung cites are substantial, but they remain targets for concept-stage technology. For buyers and AI infrastructure planners, the immediate takeaway is less about an imminent zHBM product than about the direction of travel: AI systems are likely to rely on increasingly specialized, vertically integrated memory tiers, with HBM remaining central to the highest-performance compute path. 13
14
18
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
People also ask
What is the short answer to "Samsung zHBM: Direct-Stacked AI Memory Explained"?
Samsung says zHBM could raise AI response speed by more than 10× by stacking HBM directly on an AI accelerator rather than beside it.
What are the key points to validate first?
Samsung says zHBM could raise AI response speed by more than 10× by stacking HBM directly on an AI accelerator rather than beside it. The company projects a zHBM enabled interface could deliver about 8× HBM5 performance, more than 10× memory density, 3× energy efficiency, and over 50% lower thermal resistance than conventional HBM5.
What should I do next in practice?
At the same summit, OpenAI and Intel engineers argued that CXL is better suited to supplemental capacity and colder data than to replacing HBM for active AI model execution.
Sources
asiae.co.kr"Opening the Era of 1,000 Tokens per Second"…Samsung Electronics Drives AI Semiconductor Innovation with zHBM
en.sedaily.comSamsung Touts 10-Fold AI Speed Gain With Stacked zHBM Memory
koreaherald.comSamsung stacks HBM atop AI chips in 3D memory push