Zyphra’s ZAYA1-8B-Diffusion-Preview and the Push for Faster AI Inference
Zyphra’s ZAYA1 8B Diffusion Preview converts its autoregressive ZAYA1‑8B MoE model into a diffusion language model that generates 16 tokens in parallel, with reported decoding speedups of 4.6× using a lossless sampler... The design shifts text generation from sequential token by token decoding to parallel block gene...
Published byEdited with GPT-5.5Images generated with GPT Image 2
Zyphra’s ZAYA1 8B Diffusion Preview converts its autoregressive ZAYA1‑8B MoE model into a diffusion language model that generates 16 tokens in parallel, with reported decoding speedups of 4.6× using a lossless sampler...
The design shifts text generation from sequential token by token decoding to parallel block generation, reducing memory bandwidth bottlenecks and increasing GPU utilization.
If the approach holds up in production, it could lower inference costs and accelerate reinforcement‑learning training workflows that rely on massive numbers of generated samples.
What is Zyphra’s new ZAYA1-8B-Diffusion-Preview model, how does converting its autoregressive ZAYA1-8B into a Mixture-of-Experts diffusion lDiffusion-style language models can draft multiple tokens simultaneously instead of generating them sequentially.
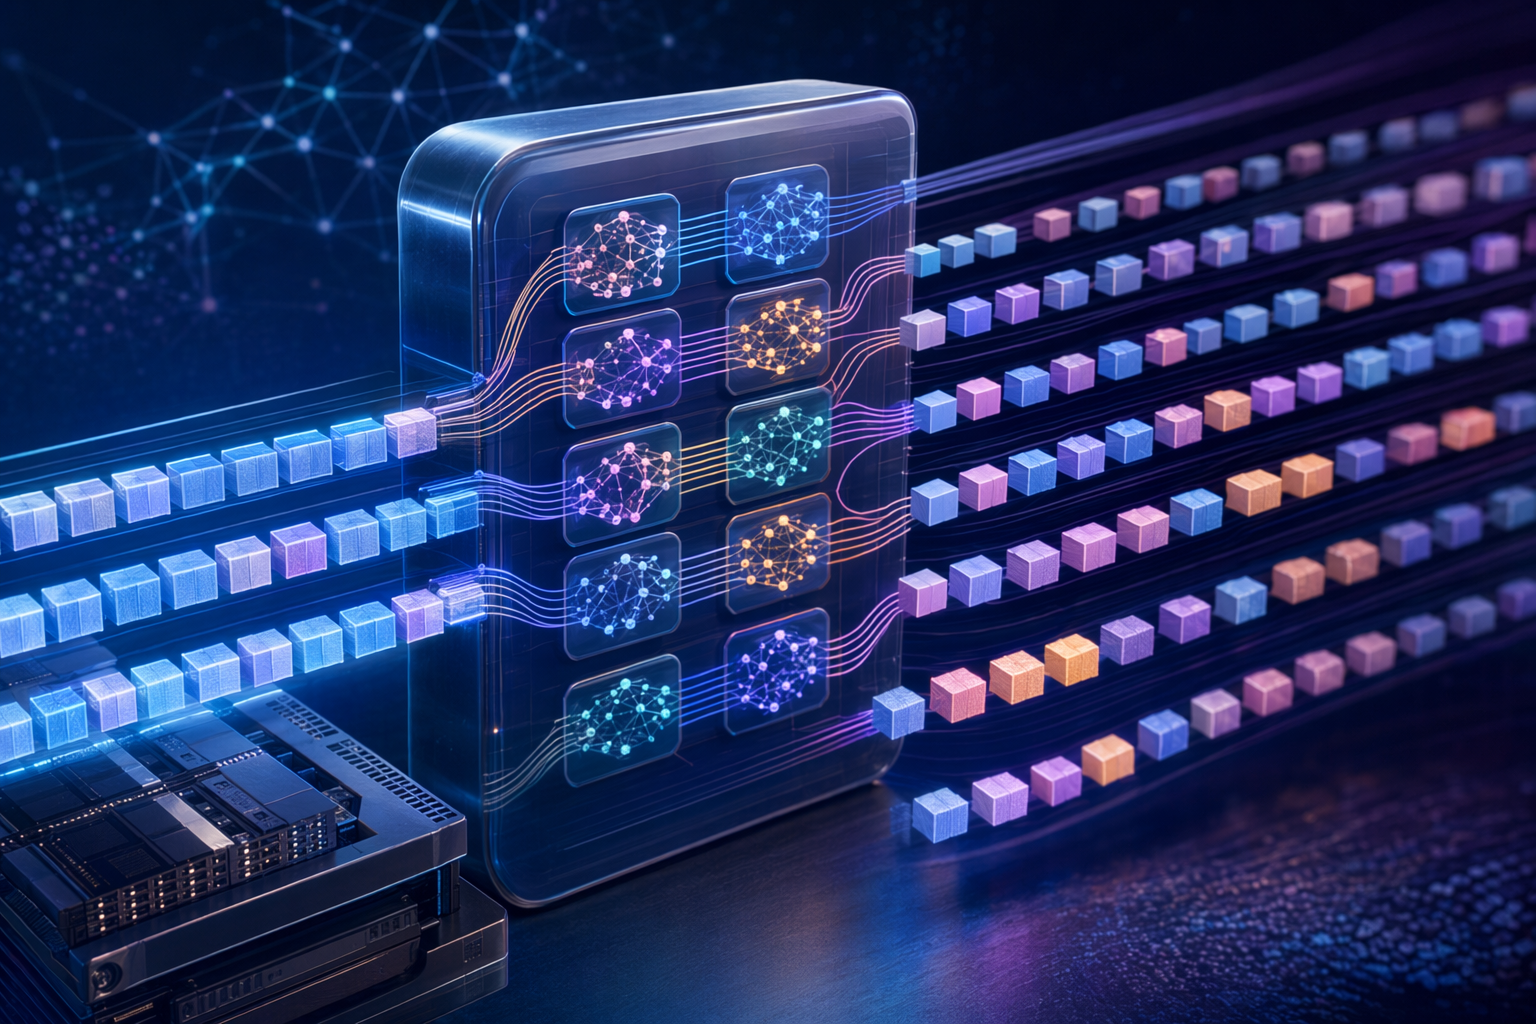
AI Prompt
Create a landscape editorial hero image for this Studio Global article: What is Zyphra’s new ZAYA1-8B-Diffusion-Preview model, how does converting its autoregressive ZAYA1-8B into a Mixture-of-Experts diffusion l. Article summary: Zyphra’s ZAYA1-8B-Diffusion-Preview is an experimental diffusion-language version of its ZAYA1-8B MoE model, designed to decode blocks of text in parallel rather than strictly one token at a time. Zyphra claims it can ge. Topic tags: general, academic, general web, user generated. Reference image context from search candidates: Reference image 1: visual subject "# Zyphra Releases ZAYA1-8B: A Reasoning MoE Trained on AMD Hardware That Punches Far Above Its Weight Class. Zyphra AI has released ZAYA1-8B, a small Mixture of Experts (MoE) langu" source context "Zyphra Releases ZAYA1-8B: A Reasoning MoE Trained on AMD Hardware That Punches Far Above Its Weight Class
openai.com
A diffusion approach to faster language model decoding
Zyphra’s ZAYA1‑8B‑Diffusion‑Preview is an experimental version of the company’s ZAYA1‑8B language model that replaces traditional autoregressive decoding with a diffusion-based generation process. Instead of producing text strictly one token at a time, the system drafts blocks of 16 tokens simultaneously, enabling substantially faster decoding under certain sampling strategies. Zyphra reports theoretical speedups of 4.6× with a “lossless” sampler and up to 7.7× with a logit‑mixing sampler, with minimal quality degradation depending on configuration.
The preview model is notable because it was converted from an existing autoregressive checkpoint rather than trained as a diffusion model from scratch, demonstrating a path for adapting conventional LLMs into diffusion-style decoders.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "Zyphra’s ZAYA1-8B-Diffusion-Preview and the Push for Faster AI Inference"?
Zyphra’s ZAYA1 8B Diffusion Preview converts its autoregressive ZAYA1‑8B MoE model into a diffusion language model that generates 16 tokens in parallel, with reported decoding speedups of 4.6× using a lossless sampler...
What are the key points to validate first?
Zyphra’s ZAYA1 8B Diffusion Preview converts its autoregressive ZAYA1‑8B MoE model into a diffusion language model that generates 16 tokens in parallel, with reported decoding speedups of 4.6× using a lossless sampler... The design shifts text generation from sequential token by token decoding to parallel block generation, reducing memory bandwidth bottlenecks and increasing GPU utilization.
What should I do next in practice?
If the approach holds up in production, it could lower inference costs and accelerate reinforcement‑learning training workflows that rely on massive numbers of generated samples.
The diffusion preview builds on ZAYA1‑8B, a mixture‑of‑experts (MoE) reasoning model released by Zyphra. The architecture contains just over 8 billion total parameters but activates only about 760 million during inference, a design intended to deliver competitive performance while keeping compute requirements relatively low.
Mixture‑of‑experts routing means only a subset of specialized neural subnetworks (“experts”) are used for each token, which can significantly reduce inference cost compared with dense models of similar scale.
Why autoregressive decoding is slow
Most large language models today use autoregressive generation. Each new token depends on the entire previously generated sequence. The process works like this:
Generate the next token.
Update the key–value (KV) cache with that token.
Repeat the process for the following token.
Because each step depends on the previous one, the system must generate tokens sequentially, which makes decoding difficult to parallelize. This often leads to memory‑bandwidth bottlenecks when repeatedly accessing the KV cache during generation.
How the diffusion model generates 16 tokens at once
Zyphra’s diffusion conversion changes the decoding process.
Instead of predicting one token at a time, the model proposes a block of candidate tokens simultaneously. In the preview release, the block size is 16 tokens per diffusion step.
The workflow roughly looks like this:
The model generates multiple candidate drafts for a block of tokens.
A sampler evaluates which tokens can be accepted.
Accepted tokens are appended to the output, and the process repeats for the next block.
Because the candidate tokens share the same prefix and KV cache state, the model can perform parallel computation for multiple tokens in a single forward pass. This shifts the workload away from memory‑bound sequential decoding and toward compute‑heavy parallel processing, which GPUs handle more efficiently.
Two sampling strategies and their speed trade‑offs
The reported performance improvements depend on the sampling method used during decoding.
Lossless sampler
Uses acceptance rules similar to speculative decoding.
Zyphra reports about 4.6× faster decoding compared with standard autoregressive generation.
Designed to avoid systematic drops in evaluation performance.
Logit‑mixing sampler
Combines logits from the diffusion and autoregressive distributions.
Improves token acceptance rates.
Zyphra reports up to 7.7× speedup, though with some potential quality degradation.
These results come primarily from Zyphra’s own technical reports and demonstrations, so independent benchmarking will be important to confirm performance across real workloads.
Why the AMD training stack matters
Another unusual aspect of the project is the hardware ecosystem used to train it. Zyphra reports that the model is the first diffusion language model trained on AMD GPUs, rather than the Nvidia infrastructure that dominates most large‑scale AI training.
The company trained the base ZAYA1‑8B model and its diffusion conversion using AMD’s AI stack, which may help demonstrate that large‑scale LLM training and experimentation can occur outside the Nvidia ecosystem. If reproducible, this could broaden hardware competition in AI infrastructure.
Compressed Convolutional Attention (CCA)
ZAYA1‑8B also incorporates a mechanism Zyphra calls Compressed Convolutional Attention (CCA). The goal is to reduce the computational cost of attention during large parallel operations.
This matters for diffusion decoding because generating multiple tokens simultaneously resembles a large prefill operation—a phase of inference that benefits from efficient attention computation. Lowering the cost of attention can therefore help make multi‑token diffusion steps more practical at scale.
Implications for inference cost
If the reported decoding improvements translate to production systems, they could significantly affect inference economics.
Faster token generation means:
More output tokens per GPU per second
Lower cost per generated token
Reduced latency for long responses
However, Zyphra notes that diffusion‑style language model inference is still less optimized than standard autoregressive stacks, so real‑world gains may differ from theoretical measurements.
Why this matters for reinforcement learning training
Large reasoning models often rely on reinforcement learning with on‑policy rollouts, where the model must generate many candidate responses during training.
Because generation speed directly determines how many rollouts can be sampled, faster decoding could:
Reduce the cost of RL training
Enable more extensive test‑time compute experiments
Allow researchers to sample more reasoning paths per prompt
In practice, inference speed is often one of the largest costs in RL‑based model training pipelines.
A new direction in efficient AI models
The ZAYA1‑8B‑Diffusion‑Preview illustrates a broader shift in AI development. Rather than focusing only on ever‑larger models, many teams are experimenting with methods that improve “intelligence per dollar.”
This example combines several efficiency strategies:
mixture‑of‑experts architectures
diffusion‑style decoding
alternative attention mechanisms
non‑Nvidia training infrastructure
If these techniques prove reliable at scale, they could reshape how future language models are optimized—not just for capability, but for throughput, cost, and hardware efficiency. For now, the model serves as an early demonstration that converting autoregressive LLMs into diffusion decoders may offer a promising path toward faster AI generation.
zyphra.comZAYA1-8B-Diffusion-Preview: Efficient Parallel Decoding ...
venturebeat.comMeet ZAYA1-8B, a super efficient, open reasoning model trained on ...
gigazine.netA new spreading language model, 'ZAYA1-8B-Diffusion-Preview,' developed with an AMD AI chip, has emerged, transforming autoregressive models into spreading models.
phemex.comZyphra's AMD-Based Diffusion Model Boosts Speed by 7.7x - Phemex