AI Model Collapse Explained: Why Synthetic Training Data Can Degrade Models
Research shows that repeatedly training AI models on synthetic data causes “model collapse,” where rare patterns vanish and models drift away from the original data distribution—unless real world data or strong priors... Recursive training amplifies sampling bias: rare events in the data distribution’s “tails” get p...
Published byEdited with GPT-5.5Images generated with GPT Image 2
Research shows that repeatedly training AI models on synthetic data causes “model collapse,” where rare patterns vanish and models drift away from the original data distribution—unless real world data or strong priors...
Recursive training amplifies sampling bias: rare events in the data distribution’s “tails” get progressively underrepresented, so later models effectively forget they ever existed.
Studies suggest even a tiny amount of genuine real world data—or prior knowledge that constrains the model—can prevent collapse by preserving evidence about those rare patterns.
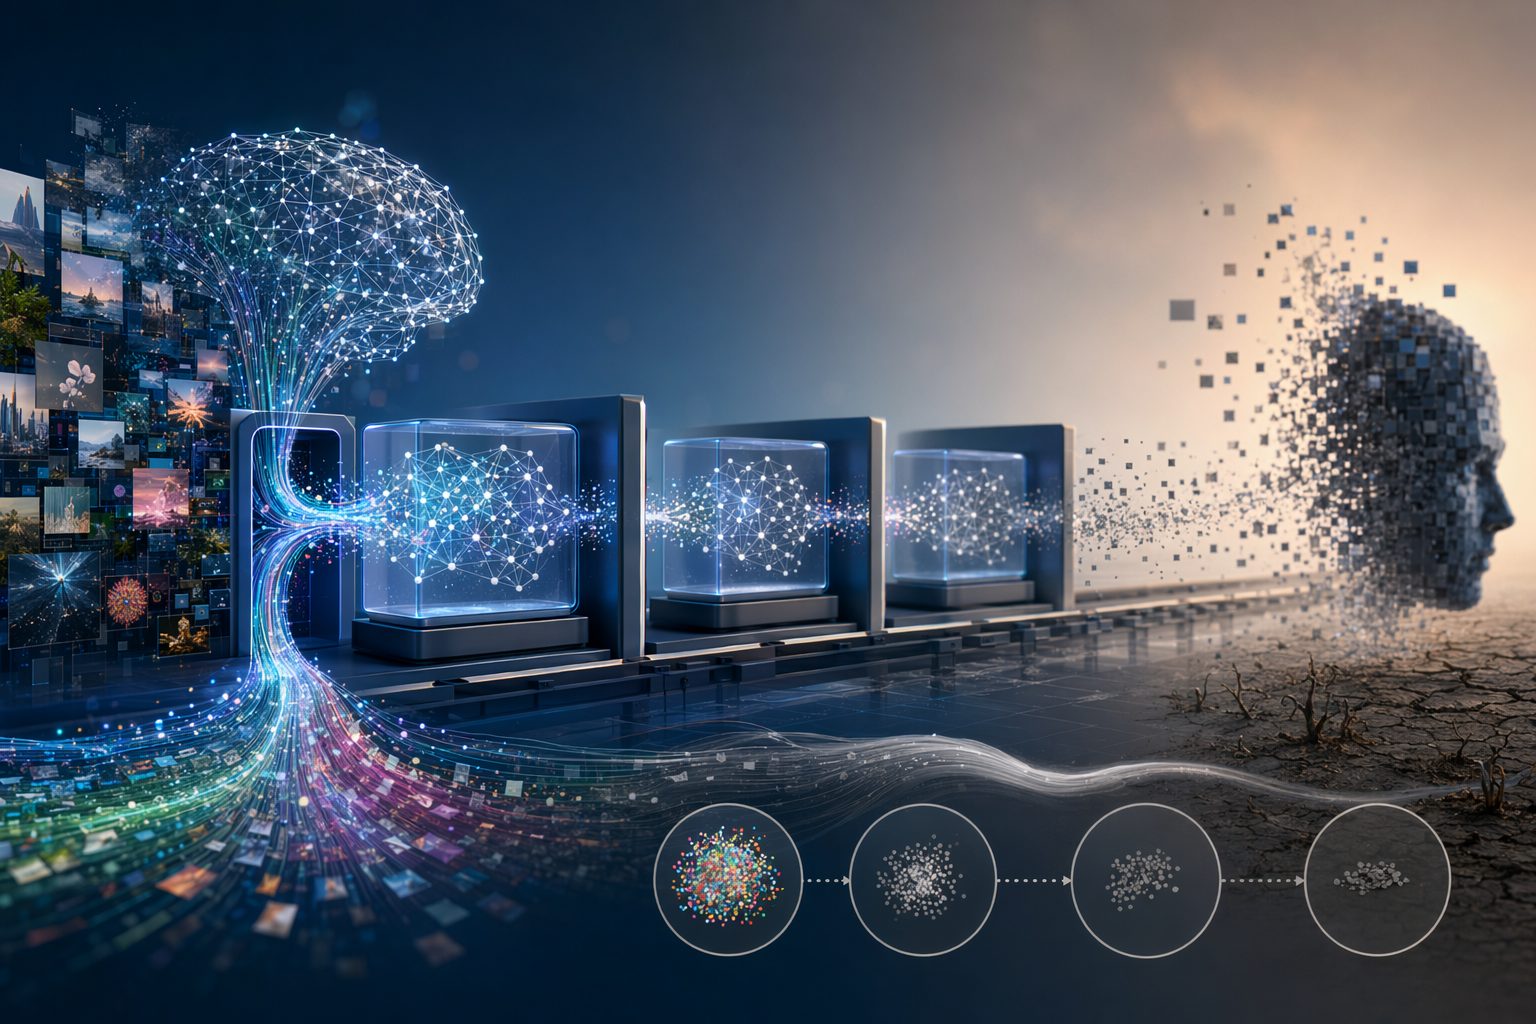
What does the new study on AI model collapse find about preventing degradation when models are trained on synthetic data, why does recursiveRecursive training on AI‑generated data can gradually erase rare patterns from a model’s learned distribution, a phenomenon researchers call model collapse.
AI Prompt
Create a landscape editorial hero image for this Studio Global article: What does the new study on AI model collapse find about preventing degradation when models are trained on synthetic data, why does recursive. Article summary: The study describes model collapse as a failure mode where recursively trained generative models lose information about the original data distribution, especially its rare or low-probability regions.. Topic tags: general, government, education, academic, general web. Reference image context from search candidates: Reference image 1: visual subject "However, as AI-generated data increasingly populates the internet, an important question arises: What happens when new AI models are trained on datasets containing their previous o" source context "Avoiding Model Collapse in AI Training - Risk Insight" Reference image 2: visual subject "Artificial intelligence models
openai.com
Generative AI systems are increasingly trained using synthetic data—content produced by earlier models. But research shows this practice carries a serious risk known as model collapse: a gradual degradation where models lose the ability to represent the full diversity of the original data.
A major study on recursive training found that when models repeatedly learn from AI‑generated outputs instead of real-world data, they begin to forget rare patterns in the underlying distribution. Over successive training cycles, these missing patterns accumulate until the model’s representation of reality becomes distorted.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "AI Model Collapse Explained: Why Synthetic Training Data Can Degrade Models"?
Research shows that repeatedly training AI models on synthetic data causes “model collapse,” where rare patterns vanish and models drift away from the original data distribution—unless real world data or strong priors...
What are the key points to validate first?
Research shows that repeatedly training AI models on synthetic data causes “model collapse,” where rare patterns vanish and models drift away from the original data distribution—unless real world data or strong priors... Recursive training amplifies sampling bias: rare events in the data distribution’s “tails” get progressively underrepresented, so later models effectively forget they ever existed.
What should I do next in practice?
Studies suggest even a tiny amount of genuine real world data—or prior knowledge that constrains the model—can prevent collapse by preserving evidence about those rare patterns.
Understanding how this happens—and how to prevent it—is becoming critical as AI-generated content spreads across the internet and begins to dominate the datasets used to train future models.
What “Model Collapse” Means
Model collapse refers to a failure mode in which generative models degrade when they are trained on data produced by previous models rather than on original human‑generated data.
Researchers found that recursive training introduces irreversible defects: the resulting models gradually lose information about the tails of the data distribution—the rare or unusual examples that appear infrequently but are essential for accurately representing reality.
Over time, the model’s outputs become narrower and less diverse, increasingly reflecting only the most common patterns in the training data.
This phenomenon has been demonstrated across several types of generative models, including:
Large language models (LLMs)
Variational autoencoders (VAEs)
Gaussian mixture models (GMMs)
The fact that multiple model families exhibit the same effect suggests that collapse is a general property of generative learning under recursive synthetic data, not a quirk of a specific architecture.
Why Recursive Training Erases Rare Patterns
The mechanism behind model collapse comes from basic statistical sampling.
When a model generates synthetic data, it tends to reproduce high‑probability patterns more often than rare ones. Rare events lie in the distribution’s tails and are already underrepresented when sampling occurs.
When the next generation of models is trained on that synthetic dataset:
Rare examples appear even less often than before.
The model learns a slightly distorted distribution.
Future generations compound the distortion.
Each iteration amplifies the bias introduced by earlier models. Eventually, the tails of the distribution disappear entirely, leaving only the dominant patterns.
Once those rare examples vanish from the training corpus, later models cannot reconstruct them because the evidence that they existed has been lost.
How Real Data or Prior Knowledge Prevent Collapse
One of the most surprising findings from recent analyses is how little real-world information may be required to prevent collapse.
Researchers studying statistical models known as exponential families found that incorporating even a single datapoint from the real distribution can anchor the training process. That datapoint preserves evidence that the missing patterns exist, preventing the recursive training loop from converging to an incorrect distribution.
Similarly, prior knowledge—constraints or assumptions built into a model—can serve a comparable role. By restricting the possible distributions the model can learn, priors stop the system from drifting entirely toward the biased patterns found in synthetic data.
In practical terms, this means:
Real-world samples help preserve rare but valid patterns.
Priors can enforce structure that synthetic data alone might erase.
Even when synthetic data vastly outnumbers real data, these anchors can stabilize training.
Why This Matters for Large Language Models
The model collapse problem has become more urgent as AI-generated content spreads across the web.
Large language models are often trained on massive internet-scale datasets. As more online text is produced by AI systems, those datasets risk becoming increasingly contaminated with synthetic outputs from earlier models.
If future models are trained primarily on this AI-generated content, they could gradually drift away from the richness and diversity of human language and knowledge.
Potential consequences include:
Reduced diversity in generated outputs
Poor handling of rare or unusual cases
A narrowing representation of real-world information
Researchers warn that preventing this outcome will require maintaining access to trusted human-generated data or incorporating mechanisms that preserve the original data distribution during training.
The Limits of Current Evidence
While the mechanism of model collapse is well supported, some details remain uncertain. For example, the claim that a single real datapoint can prevent collapse comes from theoretical analyses and simplified statistical models rather than large-scale production LLM training experiments.
That means the exact amount of real data needed in practical systems may vary depending on model architecture, dataset composition, and training procedures.
Still, the central lesson is clear: purely recursive AI training risks gradually erasing parts of reality, and maintaining a connection to real-world data is essential for keeping models accurate over time.
arxiv.org
Lost in Retraining: Roaming the Parameter Space of ...