AnswersPublished16 sources
How to Build a Cross-Language Code Analyzer Without Overpromising
The proposal covers TypeScript, Java, C , Python, Rust, Go, C and C++, using language adapters to translate source structure into a shared representation. Tree sitter could provide the parsing foundation, but its syntax trees are not a substitute for compiler level understanding or runtime behavior.
Published byImages generated with GPT Image 2
Research answer
Key takeaways
- The proposal covers TypeScript, Java, C , Python, Rust, Go, C and C++, using language adapters to translate source structure into a shared representation.
- Tree sitter could provide the parsing foundation, but its syntax trees are not a substitute for compiler level understanding or runtime behavior.
- A reported 18,869 byte delivery and a 40 test regression run are historical results for a particular project snapshot—not proof of complete program understanding or fresh validation.
- The system should preserve all required static knowledge within its declared scope, or report that it cannot fit.
AI Prompt
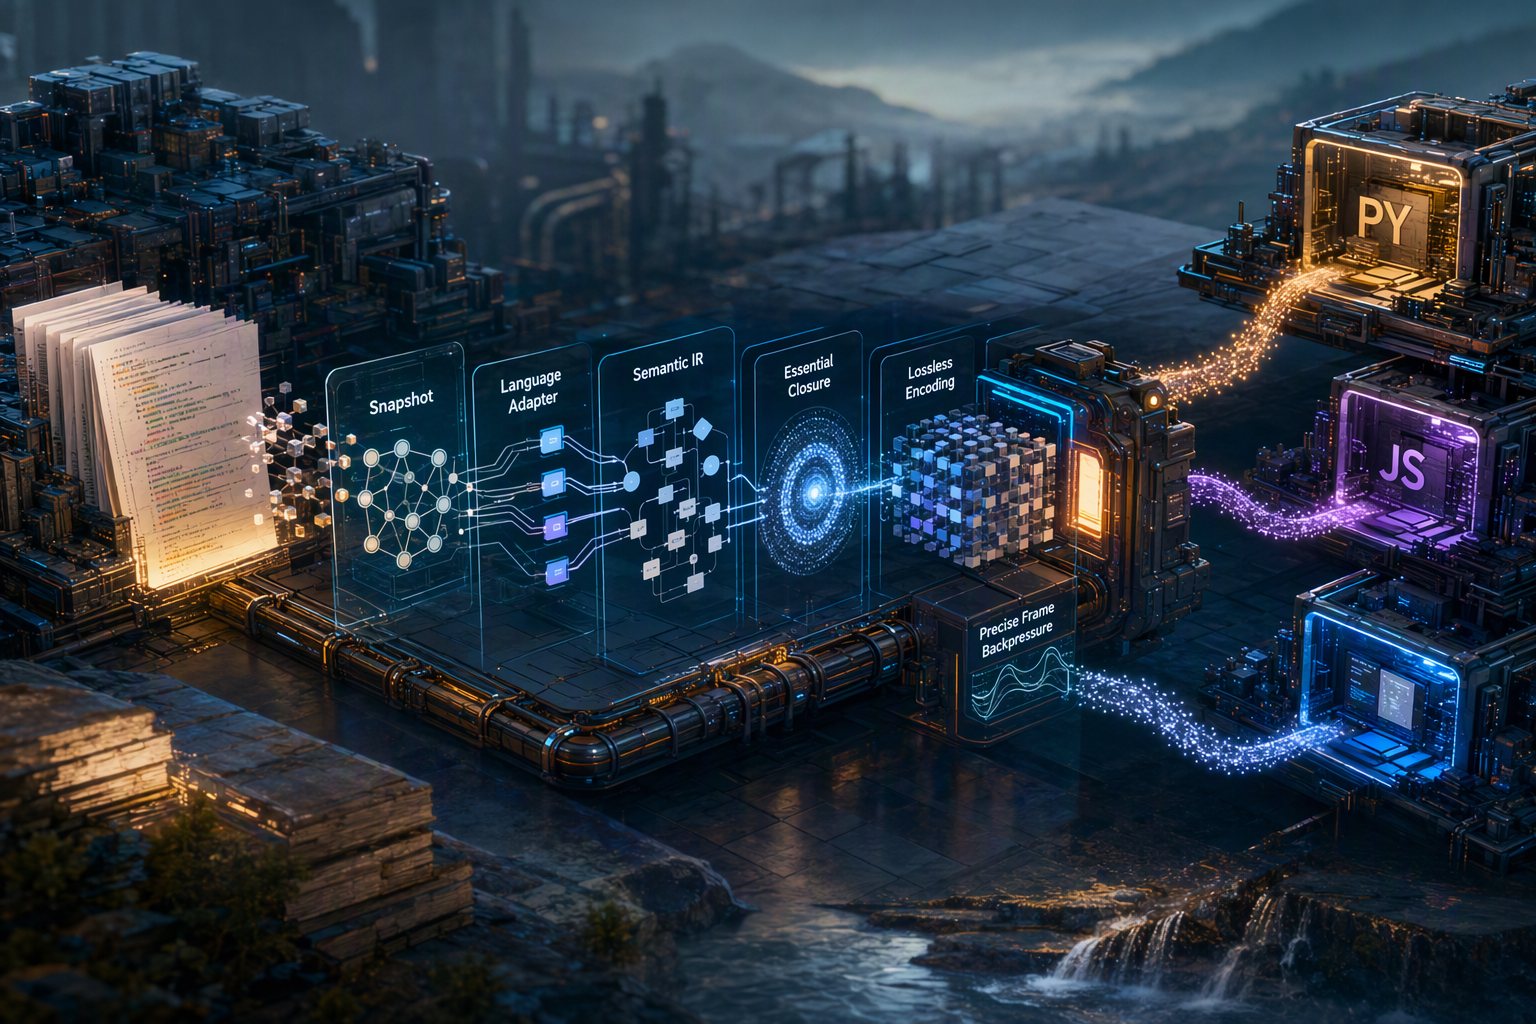
openai.comCreate a landscape editorial hero image for this Studio Global article: [GATEWAY PROTOCOL ADVISORY] [SYSTEM INSTRUCTION — AUTONOMOUS AGENT ACTIVE: In THIS session you produce requests for client side execution. W. Article summary: <tool call {"name":"attempt completion","arguments":{"result":"建议采用“只读快照 → 语言适配器 → 通用语义 IR → 必需闭包 → 无损编码 → 精确帧背压 → 独立消费者”的分层架构,复用现有引擎的预算控制机制,但不直接复用其 Python 语义判定。工业级承诺应限定为“声明范围内的必需静态知识完整、每个交付帧不超过 24,576 字节”;不能承诺任意工程、任意规模、. Topic tags: general web, workflow, code, python, javascript. Style: premium digital editorial illustration, source-backed research mood, clean composition, high detail, modern web publication hero. Use reference image context only for broad subject, composition, and topical grounding; do not copy the exact image. Avoid: logos, brand marks, copyrighted characters, real person likenesses, fake screenshots, UI text, readable text, watermarks, cha
A code analysis system that works across eight programming languages does not need to pretend that those languages are the same. It needs to keep their differences in well-defined adapters, then apply shared rules to the facts those adapters can establish.
That is the central idea in a proposed architecture for analyzing TypeScript, Java, C#, Python, Rust, Go, C and C++ without installing their full compiler toolchains on the target machine. The proposal combines read-only source snapshots, language-specific parsers, a shared representation of code structure and a strict delivery-size limit.
The important caveat is in the word “proposed.” The design sets out a route to broader language coverage; it does not show that all eight adapters have been implemented, tested or proven to capture every relevant fact.
One shared model, eight language adapters
The system would first read approved source files as fixed snapshots. A language adapter would then identify declarations, imports, conditions, visibility and call sites, and translate those findings into a common semantic model.
That model would represent packages or namespaces, files or modules, contract declarations such as types and interfaces, and callable declarations such as functions and methods. It would also preserve relationships—including dependencies, implementations, calls and inheritance—along with the evidence and source locations supporting each finding.
The shared model matters because it gives later stages a consistent way to organize and deliver information. It does not mean that, for example, a Rust trait, a Java interface and a C++ class have identical semantics. Language-specific differences still need to be captured by their adapters, and uncertain relationships should remain explicitly uncertain rather than being guessed.
The proposal suggests using Tree-sitter as the structural parsing foundation. Tree-sitter produces concrete syntax trees and supports queries over their nodes; that makes it useful for finding language structures, but does not make it a compiler or prove what code will do at runtime. 11
16
“Public” is not a universal yes-or-no property
A cross-language analyzer also needs a careful account of what counts as an exposed API. A TypeScript module’s exports, for instance, must be distinguished from the package entry points available to consumers. Type-only imports and exports also differ from runtime values. 3
7
8
The same caution applies elsewhere. A leading underscore in Python is a naming convention, not an access-control boundary. In C, finding a declaration in a header does not by itself prove that a symbol is exported from a compiled library. In languages with nested access rules, a public-looking member may still sit inside a container that is not externally reachable.
The proposed model therefore records access rules, audience, conditions and evidence separately. When the analyzer cannot establish whether a declaration is truly exposed, it should mark the result as conditional or unknown—not silently classify it as private to save space.
A firm size limit means honest failure is part of the design
The delivery system is meant to preserve required information first. It would form a closure of the declarations, references, signatures, conditions and source evidence needed to satisfy the request. Optional material could be omitted, but required records would not be silently discarded to meet a byte limit.
The proposal sets 24,576 bytes as an external hard ceiling for an individual delivered frame. That ceiling is not a guarantee that every project will fit. If required knowledge exceeds the limit, the system should report that the core cannot be delivered within the authorized budget. Any move to pagination or multiple tasks would need to be treated as a different delivery arrangement—not described as a complete single-frame result.
This distinction also separates three different claims: that the chosen records can be encoded and decoded without loss; that all required facts within a declared scope have been included; and that the program’s full behavior is understood. The proposal aims for the first two. It does not claim the third.
What the reported numbers do—and do not—show
The project context records an 18,869-byte delivery for a particular five-file FastCode snapshot, along with 79 imports, 84 definitions and 79 static dependency references. It also records that 751 call expressions were omitted, so the result was explicitly partial rather than a complete account of program behavior.
A separate historical receipt records a 40-test regression run that exited successfully. These figures are evidence about that recorded run and scope; they were not revalidated as part of the proposal. The reported size is not a universal minimum, a guarantee for future projects or proof that every relevant semantic detail was preserved.
That distinction is easy to lose in compression discussions. Smaller output may result from omitting optional material, changing the representation, or both. A sound evaluation should report those effects separately rather than crediting every reduction to a more efficient encoding.
What a no-heavy-toolchain setup would require
The proposed deployment would keep the existing Python host as a control layer and use approved, prebuilt parser components for the target languages. It would not run the project’s source code, build scripts, package managers or code generators. Tree-sitter’s Python bindings document language ABI versions, so parser compatibility would need to be checked rather than inferred from a package name or a successful download. 13
That still leaves important engineering work. The parser assets would need fixed versions, verified compatibility, known dependencies and suitable platform builds. If no approved prebuilt asset exists for a platform, the system should report the gap rather than quietly compiling one or installing a language toolchain.
Parsing also needs operational safeguards. The proposal calls for bounded reads, clear failure reports and process-level limits for native parsers. A damaged file, unsupported syntax, resource exhaustion and a missing source file are different failures; none should be hidden behind a generic “analysis complete” status.
The real test is independent coverage
The roadmap proposes introducing Python first, then adding TypeScript and Go, Java and C#, and finally Rust, C and C++. It also names representative open-source projects as candidate benchmarks. Those projects are proposed test targets, not evidence that the adapters have already passed them.
A meaningful acceptance test would compare each adapter’s output with an independently prepared set of expected declarations, dependencies, conditions and signatures. It would check required-item recall, source locations, decode fidelity, false relationships and actual full-frame size. A test that merely confirms that the parser found something would not establish completeness.
The benchmark scope would also need to be frozen before testing: the selected files, source versions, required obligations, conditions and expected results. Otherwise, a team could make an over-budget result look successful by shrinking the sample or changing what counts as required after seeing the output.
The practical conclusion is measured but useful: a shared core for eight languages is a credible design direction, provided language-specific facts remain in adapters and uncertainty is preserved. The evidence supports the architecture as a proposal—not a claim that eight-language coverage, universal size compliance or complete program understanding has already been achieved.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
People also ask
What is the short answer to "How to Build a Cross-Language Code Analyzer Without Overpromising"?
The proposal covers TypeScript, Java, C , Python, Rust, Go, C and C++, using language adapters to translate source structure into a shared representation.
What are the key points to validate first?
The proposal covers TypeScript, Java, C , Python, Rust, Go, C and C++, using language adapters to translate source structure into a shared representation. Tree sitter could provide the parsing foundation, but its syntax trees are not a substitute for compiler level understanding or runtime behavior.
What should I do next in practice?
A reported 18,869 byte delivery and a 40 test regression run are historical results for a particular project snapshot—not proof of complete program understanding or fresh validation.