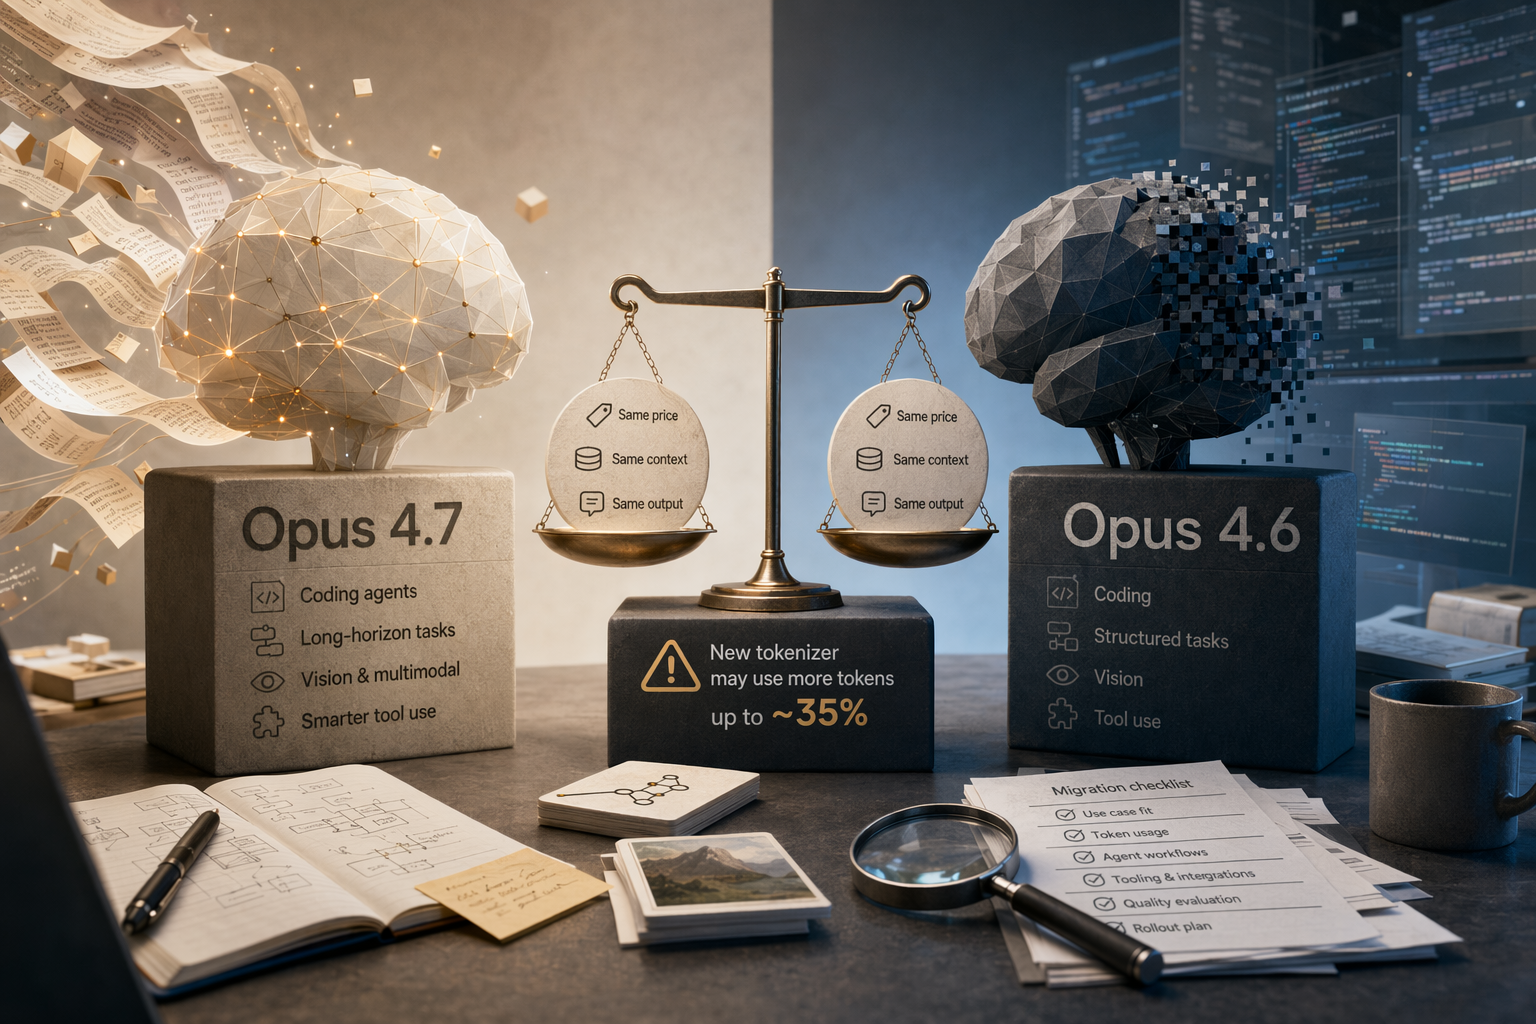
Claude Opus 4.7 and Opus 4.6 have the same standard Claude API list price: $5 per million input tokens and $25 per million output tokens; both also support a 1M token context window and 128k max output.[16][15] The real cost can still change because Opus 4.7 uses a new tokenizer that may use roughly 1x to 1.35x as m...
Published byEdited with GPT-5.5Images generated with GPT Image 2
Claude Opus 4.7 and Opus 4.6 have the same standard Claude API list price: $5 per million input tokens and $25 per million output tokens; both also support a 1M token context window and 128k max output.[16][15]
The real cost can still change because Opus 4.7 uses a new tokenizer that may use roughly 1x to 1.35x as many tokens when processing text, depending on the content.[1]
Opus 4.7 is most worth testing for coding agents, long running tool workflows, and vision heavy tasks; production users must also migrate away from the old extended thinking syntax, which returns a 400 error on Opus 4...
Claude Opus 4.7 vs Opus 4.6:同價但未必同成本,升級前睇清 6 點Claude Opus 4.7 與 Opus 4.6 的升級重點在 tokenizer、vision、agent workflow 和 API 遷移,而不只是標價。
AI Prompt
Create a landscape editorial hero image for this Studio Global article: Claude Opus 4.7 vs Opus 4.6:同價但未必同成本,升級前睇清 6 點. Article summary: Claude Opus 4.7 唔係靠更大 context 或更平價格取勝:兩者標價同為 $5/$25 每百萬 input/output tokens,context/output 也同為 1M/128k。真正值得升級的是 coding agent、長流程任務與 vision;但 4.7 新 tokenizer 可能令同一文字多用最多約 35% tokens。[16][15][1]. Topic tags: ai, anthropic, claude, coding agents, agents. Reference image context from search candidates: Reference image 1: visual subject "# Claude Opus 4.7 vs Opus 4.6. Head-to-head comparison of Claude Opus 4.7 vs Opus 4.6: benchmark deltas, pricing, effort levels, vision, tokenizer, and a migration checklist. Opus" source context "Claude Opus 4.7 vs Opus 4.6 - LLM Stats" Reference image 2: visual subject "用大家的话说,就是Ahthropic发了一个价格比4.6贵上50%的模型,性能还更差。 它出现了严重的幻觉,在计算密集型项目上极其拉胯,不仅比不上Opus 4.6,甚至让人" source context "Claude Opus 4.7,全网差评!刚升级就翻车,用户怒斥:还我4.6 - 知乎" Style:
openai.com
The easiest mistake with Claude Opus 4.7 is to assume that “same price” means “same cost,” or that “newer model” means every workflow should move immediately.
Anthropic’s pricing docs list Claude Opus 4.7 and Opus 4.6 at the same standard Claude API list price: $5 per million input tokens and $25 per million output tokens. The migration guide also says Opus 4.7 keeps the same 1M-token context window and 128k max output limit as Opus 4.6.
But the upgrade is not just a pricing-table question. Opus 4.7 brings a new tokenizer, task budgets, high-resolution image support, and an API change that can break older extended-thinking integrations. The practical question is whether it improves your real tasks enough to reduce retries, errors, human review, and unnecessary tool calls.
Studio Global AI
Continue your research
This page includes a source-backed answer you can continue inside Studio Global.
What is the short answer to "Claude Opus 4.7 vs. Opus 4.6: Should You Upgrade?"?
Claude Opus 4.7 and Opus 4.6 have the same standard Claude API list price: $5 per million input tokens and $25 per million output tokens; both also support a 1M token context window and 128k max output.[16][15]
What are the key points to validate first?
Claude Opus 4.7 and Opus 4.6 have the same standard Claude API list price: $5 per million input tokens and $25 per million output tokens; both also support a 1M token context window and 128k max output.[16][15] The real cost can still change because Opus 4.7 uses a new tokenizer that may use roughly 1x to 1.35x as many tokens when processing text, depending on the content.[1]
What should I do next in practice?
Opus 4.7 is most worth testing for coding agents, long running tool workflows, and vision heavy tasks; production users must also migrate away from the old extended thinking syntax, which returns a 400 error on Opus 4...
New tokenizer, task budgets, high-resolution image support
These are the upgrade variables that can affect real workflows.
Thinking API compatibility
Some integrations may still use older extended thinking syntax
Old thinking: {type: "enabled", budget_tokens: N} is no longer supported
That old syntax returns a 400 error on Opus 4.7 or later; migrate to adaptive thinking.
1. The list price is the same, but your bill may not be
If you only check the pricing page, Claude Opus 4.7 does not look more expensive than Opus 4.6. Both are listed at $5 per million input tokens and $25 per million output tokens under standard Claude API pricing.
That does not guarantee the same monthly bill. Anthropic’s Opus 4.7 documentation says the model uses a new tokenizer. When processing text, it may use roughly 1x to 1.35x as many tokens as previous models, depending on the content. Anthropic also says /v1/messages/count_tokens will return different token counts for Opus 4.7 than for Opus 4.6.
So the cost test is not “does the pricing table match?” It is: take your own prompts, documents, tool calls, and expected outputs, then count tokens again. For long prompts, long outputs, batch jobs, and agent workflows, tokenizer differences can change the actual invoice even when the published per-token price is identical.
2. Context and output limits did not get bigger
If your main reason to upgrade is a larger context window, Opus 4.7 is probably not the change you are waiting for. Anthropic’s migration guide says Opus 4.7 supports the same 1M-token context window and 128k max output tokens as Opus 4.6.
The same guide also says Opus 4.7 supports the same broad set of features as Opus 4.6, including adaptive thinking, prompt caching, batch processing, the Files API, PDF support, vision, and server-side and client-side tools.
That means the upgrade case should not be based on a headline spec doubling. It should be based on end-to-end performance: task success rate, retry rate, tool-call efficiency, visual understanding, latency, and real token cost.
3. Coding agents and long-running workflows should test first
Public material around Opus 4.7 emphasizes complex reasoning, agentic coding, long-running tasks, instruction following, and vision work. Anthropic also says developers can access the model through the Claude API using claude-opus-4-7.
That makes Opus 4.7 most interesting if you already use Opus 4.6 for work such as:
coding agents and repository-level code analysis;
debugging, refactoring, and test repair;
multi-step tool use;
long-running agent workflows;
tasks where following detailed instructions matters more than conversational polish.
For these workflows, do not judge the upgrade by whether one answer “looks better.” Judge it by whether the model reaches the right result in fewer attempts, chooses tools more reliably, and needs less human correction. Even if token counts rise in some cases, a model that completes a task in fewer rounds may still be cheaper overall. But that has to be proven on your workflow, not inferred from the model name.
4. Vision-heavy work is another strong reason to test
Opus 4.7 adds high-resolution image support. Anthropic’s documentation says image limits increased from 1568px / 1.15MP to 2576px / 3.75MP. The migration guide also confirms that Opus 4.7 retains PDF support, vision, computer use, and related tool capabilities from Opus 4.6.
That matters most for tasks such as:
screenshot analysis;
UI review and design QA;
PDF or scanned-document understanding;
computer-use automation;
reading small text, dense tables, or interface details in images.
If your inputs are mostly plain text, this may not feel like a major upgrade. If you regularly feed Claude screenshots, product interfaces, document images, or scanned material, Opus 4.7 deserves an early A/B test.
5. Task budgets are mainly an agent-workflow feature
Opus 4.7 introduces task budgets. That is most relevant when a model is doing multi-step work, using tools, consuming many tokens, or operating inside boundaries you want to control.
For ordinary one-shot chat, short rewriting, or simple summaries, task budgets may not change the day-to-day experience much. For repeatable agent tasks—batch analysis, code repair, data cleanup, or toolchain automation—they are worth testing alongside cost monitoring.
6. Production upgrades have a breaking change
Opus 4.7 is not a completely frictionless drop-in replacement. Anthropic’s migration guide says the older extended thinking format, thinking: {type: "enabled", budget_tokens: N}, is no longer supported on Claude Opus 4.7 or later models and returns a 400 error. The guide says to migrate to adaptive thinking instead.
If your Opus 4.6 integration still depends on that old thinking syntax, do not switch production traffic first and debug later. At minimum:
update the integration in staging to use adaptive thinking;
run your regression tests;
check API errors, output formats, tool calls, latency, and token cost.
For production systems, model quality is only half the upgrade. The other half is making sure your old prompts, tools, monitoring, and cost assumptions still hold.
Do not overread “latest Opus”
Opus 4.7 is a newer Opus model, but that does not mean it represents Anthropic’s highest capability across every internal or limited-release system. The Verge reported that Anthropic’s system card said Opus 4.7 did not advance the company’s overall “capability frontier,” because the restricted Claude Mythos Preview scored higher on relevant evaluations.
That does not make Opus 4.7 irrelevant. It simply means “newest generally available Opus” should not be translated into “best for every possible task.” The concrete differences to test are still tokenizer behavior, high-resolution vision, task budgets, agentic coding performance, long-workflow reliability, and API migration requirements.
Who should upgrade first?
Prioritize Opus 4.7 testing if you:
use Opus for coding agents, debugging, refactoring, or repository analysis;
run long agent workflows with multiple tool calls;
regularly process screenshots, UI images, PDFs, scans, or other visual material;
want to test task budgets as part of agent cost control;
can update thinking integrations before production rollout.
You can probably wait if you:
mainly use Claude for chat, writing, short Q&A, or standard summarization;
already have stable Opus 4.6 prompts and a high switching cost;
are extremely sensitive to token usage and may be affected by the new tokenizer;
do not have time to handle regression testing, monitoring, or the old-thinking migration.
A 30-minute A/B test before you switch
A small real-world test is better than a generic benchmark. Before changing your default model:
Choose 5 to 10 real tasks. Use production-like prompts, documents, screenshots, and tool setups—not toy demos.
Run the same inputs on Opus 4.6 and Opus 4.7. Keep system prompts, tools, files, and sampling settings as consistent as possible. For Opus 4.7, use the claude-opus-4-7 model ID.
Record workflow metrics. Track success rate, error rate, number of human correction rounds, tool-call count, input tokens, output tokens, latency, and API errors.
Recalculate token cost with official counting. Because Opus 4.7’s tokenizer can produce different token counts from Opus 4.6, do not estimate cost only from the shared list price.
Set a rollout threshold. Make Opus 4.7 the default only if higher success rates, better outputs, or lower human effort clearly offset tokenizer changes and migration work.
Bottom line
Claude Opus 4.7 is a workflow upgrade more than a pricing or context-window upgrade. The standard API list price is the same as Opus 4.6, and the 1M context window and 128k max output limit are also unchanged. The real changes are the new tokenizer, high-resolution image support, task budgets, and the required move away from legacy extended thinking syntax.
If you are building coding agents, long-running tool workflows, or vision-heavy systems, Opus 4.7 is worth testing early and may be worth adopting. If your use case is mostly chat, writing, or summarization, there is no need to upgrade blindly: run a small A/B test with your own prompts and let the total workflow cost decide.